The SIMT and blocked models each capture one end of the spectrum, but the features that matter most on recent GPUs operate at a granularity neither provides. Warp specialization splits work across cooperating warp groups; TMA introduces dedicated agents for memory movement; TMEM creates new communication patterns between execution groups; clusters let multiple CTAs cooperate inside a shared execution context. Organizing a kernel around these features means reasoning about how several execution agents cooperate, communicate, and synchronize — a level of structure that sits between CUDA and Triton.
CUDA's SIMT model operates at too fine a granularity: it offers complete control, but every execution relationship must be written by hand. Triton's blocked model operates at too coarse a granularity: it is more productive, but turns many execution structures into implicit compiler decisions. Modern hardware increasingly calls for something in between.
We refer to that model as Multiple Instructions, Multiple Warps (MIMW). MIMW makes the warp group the fundamental unit of orchestration: instead of reasoning about individual threads or whole blocks, programmers express how multiple execution agents cooperate, communicate, synchronize, and share resources. This is the natural level at which many Hopper and Blackwell optimizations are expressed, and it is the abstraction layer TLX implements.
Figure 2 traces the evolution of GPU programming models. CUDA exposed execution directly at thread granularity, giving developers full control over scheduling, synchronization, and memory movement. Triton moved toward a SIMB model, raising the abstraction to blocked tensor computations and improving productivity. MIMW occupies the space between the two extremes, treating warp groups rather than threads or tensor blocks as first-class execution agents.
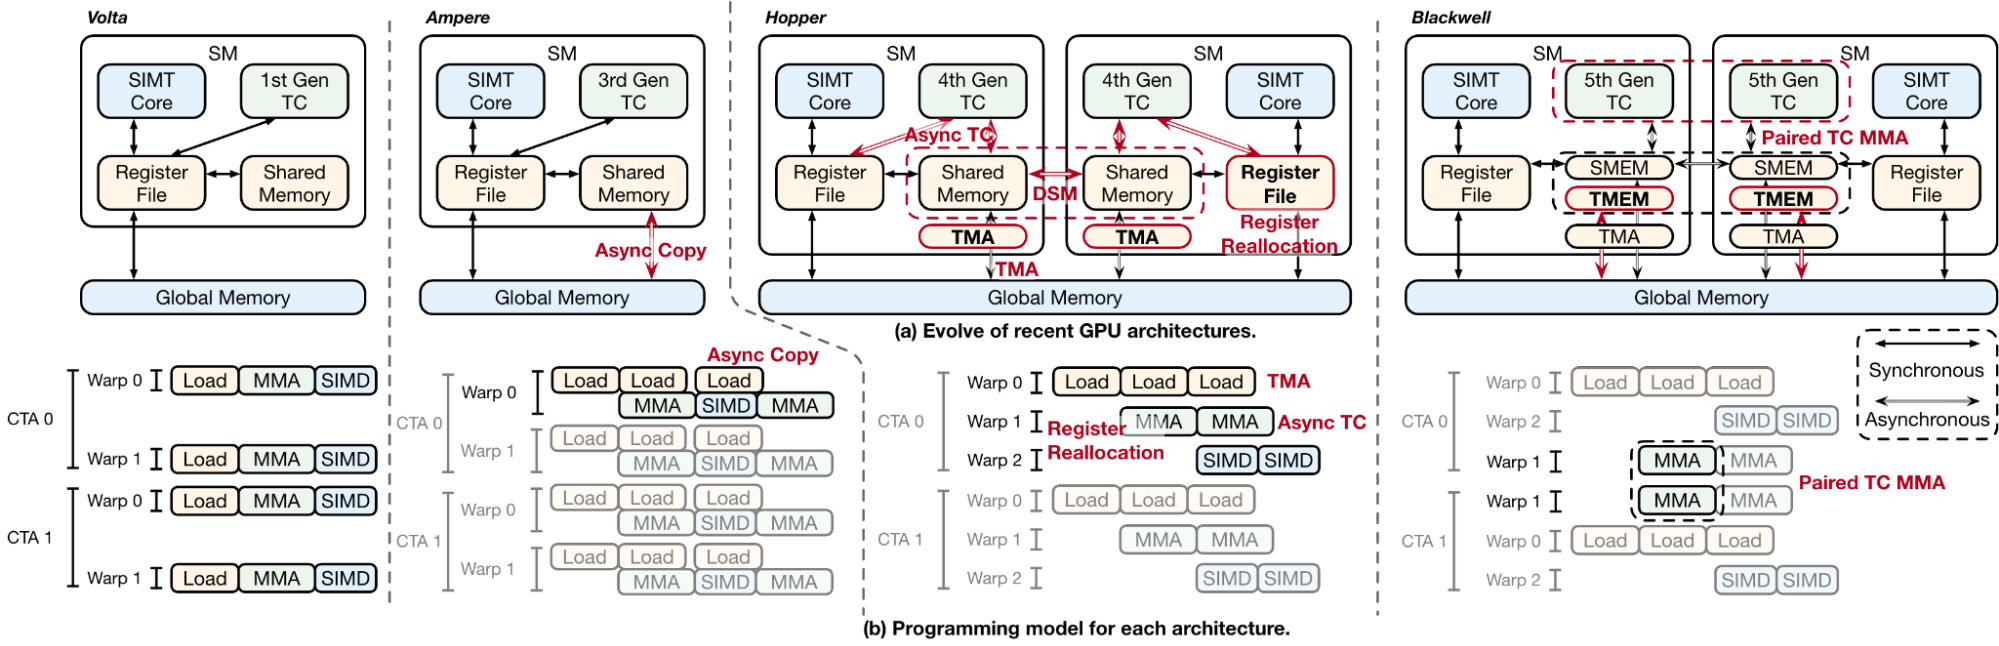
MIMW is not a software-design preference; it follows from how the hardware itself has evolved. Volta and Ampere exposed tensor cores through thread- and warp-level programming. Hopper made asynchronous data movement (enabled by TMA) and warp-group execution (enabled by WGMMA) central to high-performance kernels. Blackwell pushes further with TMEM, register reallocation, cluster execution, and paired-CTA MMA. Each generation moves more cooperation across warp groups — and sometimes across CTAs — into territory that the programming model, not just the compiler, has to address.
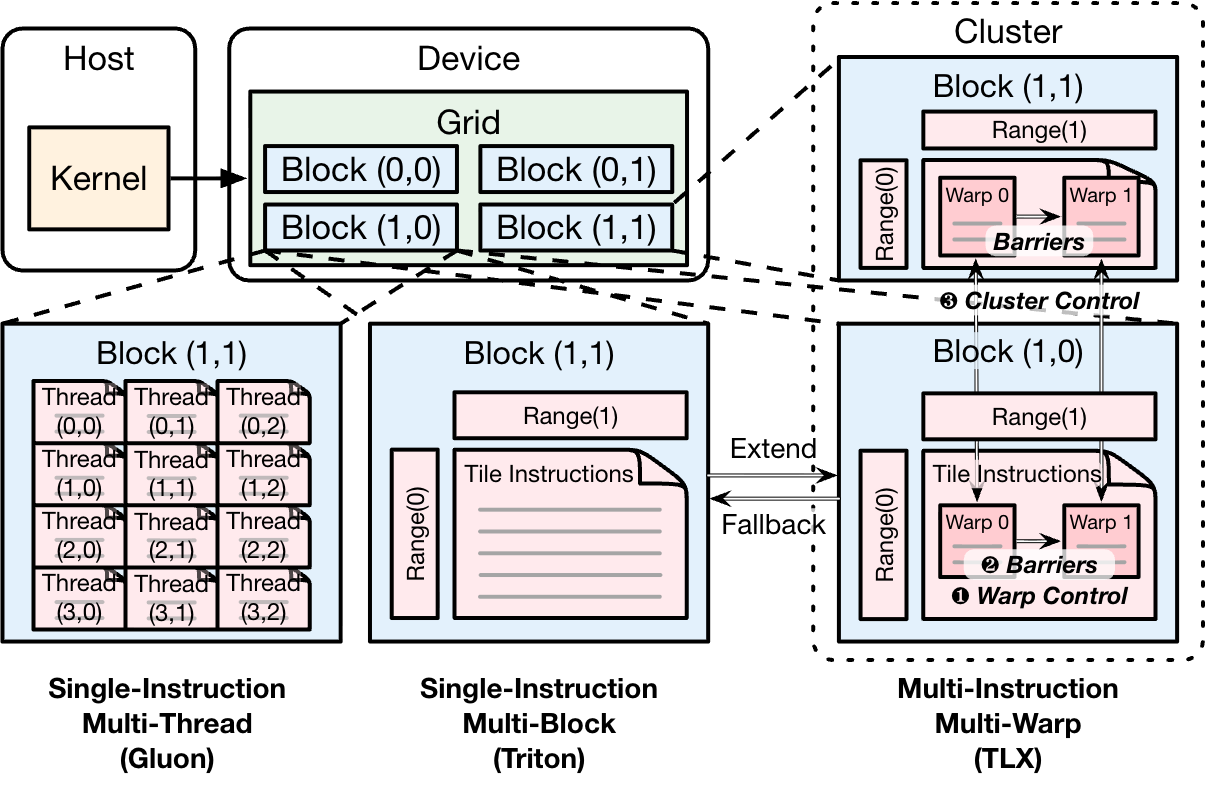
Making MIMW practical requires treating cooperating warp or wave groups as first-class execution tasks, with explicit control over shared-memory buffer access, synchronization, and handoff between them. TLX brings these capabilities into Triton's existing tensor programming model, so explicit execution control can be combined with familiar high-level tensor operations.
TLX as a Second Layer over Triton
TLX is not another standalone low-level language. Instead, it extends Triton with an additional layer of execution-oriented constructs. Programmers keep expressing computation through familiar Triton tensor operations and use TLX only where explicit control over execution, memory movement, or synchronization is needed. Triton answers what computation should be performed; TLX answers how that computation should be orchestrated. The split is easiest to see in a simple tiled matrix multiplication. In standard Triton, execution follows a synchronous load-compute loop: each tile is loaded, consumed, and discarded before the next tile begins.
# Standard Triton: synchronous load-compute loop semantics,
# with compiler-managed software pipelining
@triton.jit
def matmul_kernel(a_ptr, b_ptr, c_ptr, M, N, K, ...):
    pid_m = tl.program_id(0)
    pid_n = tl.program_id(1)
    acc = tl.zeros((BLOCK_M, BLOCK_N), dtype=tl.float32)
    for k in range(0, K, BLOCK_K):
        a = tl.load(a_ptr + ...)   # Load A tile from global memory
        b = tl.load(b_ptr + ...)   # Load B tile from global memory
        acc += tl.dot(a, b)        # Compute matmul
    tl.store(c_ptr + ..., acc)
TLX keeps the same computation but makes the execution structure explicit. Producer warp groups move data asynchronously, consumer warp groups perform tensor-core computation, and synchronization is expressed directly through lightweight barriers. The computation itself remains Triton; only the orchestration layer changes. The result is a deeply pipelined kernel that overlaps memory movement, computation, and output processing without leaving Python or giving up Triton's autotuning infrastructure. More importantly, the execution structure is visible in the source code rather than hidden inside compiler heuristics.
# TLX on Blackwell: explicit warp-group orchestration and pipelining
@triton.jit
def matmul_kernel(desc_a, desc_b, desc_c, M, N, K, ...):
    buffers_a = tlx.local_alloc((BLOCK_M, BLOCK_K), tl.float16, NUM_STAGES)
    buffers_b = tlx.local_alloc((BLOCK_K, BLOCK_N), tl.float16, NUM_STAGES)
    acc = tlx.local_alloc((BLOCK_M, BLOCK_N), tl.float32, 1, tlx.storage_kind.tmem)
    load_bars = tlx.alloc_barriers(num_barriers=NUM_STAGES, arrive_count=1)
    dot_bars  = tlx.alloc_barriers(num_barriers=NUM_STAGES, arrive_count=1)
    with tlx.async_tasks():
        # Warp group 0: PRODUCER — async TMA loads into shared memory
        with tlx.async_task("default"):
             # Wait for last matmul
            tlx.barrier_wait(dot_bars[num_k_tiles - 1], phase)
            result = tlx.local_load(acc[0])
            desc_c.store(offsets, result.to(tl.float16))

        # Warp group 1: CONSUMER — tensor-core matmul from shared memory
        with tlx.async_task(num_warps=1):
            for k in range(num_k_tiles):
                buf = k % NUM_STAGES
                 # Wait for TMA load to complete
                tlx.barrier_wait(load_bars[buf], phase)
                tlx.async_dot(buffers_a[buf], buffers_b[buf], acc[0],
                              use_acc=(k > 0), mBarriers=[dot_bars[buf]])

        # Warp group 2: EPILOGUE — store result to global memory
        with tlx.async_task(num_warps=1):
            for k in range(num_k_tiles):
                buf = k % NUM_STAGES
                 # Wait for consumer to release buffer
                tlx.barrier_wait(dot_bars[buf], phase)
                tlx.barrier_expect_bytes(load_bars[buf], ...)
                tlx.async_descriptor_load(desc_a, buffers_a[buf], offsets, load_bars[buf])
                tlx.async_descriptor_load(desc_b, buffers_b[buf], offsets, load_bars[buf])
What TLX Adds to Triton
- Warp-group orchestration: Warp groups become first-class execution agents with explicitly assigned roles — for example, producer warp groups that move data, consumer warp groups that run tensor-core computation, and epilogue warp groups that process results.
- Synchronization: Dependencies between cooperating execution groups — such as producer-consumer relationships in a software pipeline — are expressed at the warp-group level rather than the thread level, using hardware primitives such as mbarriers. Fine-grained thread-level synchronization stays with the underlying execution model and compiler, so developers coordinate the larger execution structures that increasingly determine performance on modern GPUs.
- Memory orchestration: Direct access to TMA, asynchronous tensor-core operations, and TMEM lets memory movement and computation overlap naturally inside the execution structure the program defines, while avoiding much of the low-level setup and bookkeeping typical of CUDA.
- Cluster execution: Cluster-level execution is exposed as a first-class construct. Multiple CTAs can cooperate through distributed shared memory and cluster-wide synchronization primitives, enabling on-chip communication patterns that would otherwise require global-memory round trips.
- Optional layout: Unlike CUDA and CUTLASS, TLX does not require layouts to be specified before computation can be expressed. The compiler infers reasonable defaults, and programmers specify layouts only to override them for performance. A correct kernel can be written with no layout annotations at all, with layout tuning added incrementally during optimization.
One important consequence is that kernel fusion gets significantly easier. Fusion is among the most effective GPU optimizations because it removes intermediate memory traffic and kernel launch overhead. In traditional CUDA-style workflows, however, layout management tends to dominate fusion work: each stage may assume a different tiling, swizzling, or shared-memory mapping, forcing programmers to reconcile layouts manually across operation boundaries. Because TLX infers layouts automatically, operations can often be fused without that manual reconciliation — the compiler resolves layout compatibility where it can, and programmers intervene only when a particular layout choice improves performance. That lowers the engineering effort needed for complex fused kernels and enables multi-stage pipelines that would otherwise require multiple kernels or substantial layout-specific infrastructure.
Taken together, these capabilities place TLX between Triton's productivity and CUDA's control: developers keep Python, autotuning, and blocked tensor programming while gaining direct access to the execution structures that increasingly determine performance on modern GPUs.
Production Deployments
TLX has been running across Meta's ML infrastructure for several months. Three deployments — RecSys training, RecSys inference, and large-scale LLM pretraining — show different sides of what the compiler enables.
| Case study | Hardware | Problem TLX Addresses | Headline Results | Deployment |
| GEM Model Training | NVIDIA Blackwell | Reaching roofline MFU on heterogeneous RecSys foundation models needs warp specialization and explicit tensor-memory control beyond standard Triton. | 20-25% E2E MFU on thousands of GPUs | GEM training stack. |
| In-Kernel Broadcast Optimization (IKBO) | NVIDIA Hopper | User features replicated many times per candidate batch, wasting bandwidth and compute; eliminating it needs warp-specialized multi-stage fusion. | Up to 2/3 net-latency reduction in compute-intensive latency for co-designed models. | RecSys inference, early→late ranking, GPU. |
| Distributed Grouped GEMM for LLM Pretraining | NVIDIA Blackwell | Expert-parallel MoE layers require grouped GEMM with inter-node communication; existing implementations leave performance on the table at scale. | Production-validated at large-fleet scale over an extended period. | LLM pretraining. |
GEM Training: Model-Kernel Co-Design
Meta's Generative Ads Model (GEM) is harder to optimize than LLM training: input shapes are smaller, layers carry 10+ norms, module types are heterogeneous, and architectural diversity limits MFU. A systematic co-design effort spanning model architecture, custom kernels, compiler optimizations, and hardware-specific tuning brought the latest GEM version to O(10^24) total training flops on several thousand NVIDIA Blackwell GPUs at 20-25% E2E MFU.
Choosing a Programming Model
On Blackwell, we evaluated CUTLASS, CuTeDSL, and TLX. TLX offered the best productivity-performance balance for most kernels, pairing Triton-like simplicity, autotuning, and composability with direct access to Blackwell features such as async_dot, tensor memory operations, and mbarrier synchronization. For Generalized Dot Product Attention (GDPA), TLX reached near-optimal performance with far less implementation complexity, unifying the model's many attention-like operations into a single kernel for up to 2x forward speedup.
Beyond individual kernels, TLX let us kernelize and fuse larger model regions. In GEM workloads, cutting memory movement often pays more than optimizing compute alone, so composability and fusion became first-class concerns. To speed this up, we built Agent for Compute Efficiency (ACE), an AI-assisted framework that automates profiling, analysis, and tuning, shortening the optimization cycle per kernel and freeing engineers to pursue higher-level opportunities instead of low-level performance debugging.
RecSys Inference: Eliminating Broadcast Overhead
In RecSys inference, user features are identical across scored candidates but are typically replicated dozens of times per batch to match the candidate dimension. Across a wide range of candidate-to-user broadcast ratios, this replication wastes memory bandwidth and compute, with overhead scaling linearly in candidate count.
In-Kernel Broadcast Optimization (IKBO) removes the waste by moving the broadcast into the kernel: kernels consume user and candidate inputs at their natural, mismatched batch sizes and broadcast implicitly during computation. The approach relies on co-designing the model architecture, inference runtime, and kernel implementation.
Kernel-Level Results
For the linear compression kernel, earlier work — matmul decomposition, memory alignment, and broadcast fusion — left a single bottleneck. A warp-specialized, multi-stage TLX kernel closed it with a 4x speedup on the NVIDIA H100, collapsing the whole computation into one persistent mega-kernel. Producer and consumer warp groups run concurrently under ping-pong scheduling; user and candidate GEMMs share circular buffers and synchronize through mbarriers without draining the pipeline between stages, while tile-level release-acquire synchronization coordinates across CTAs.
For FlashAttention, IKBO co-design amortizes K/V reads across candidates sharing one user context, shifting the kernel from I/O-bound to compute-bound. TLX adds FA3-style warp specialization with persistence to eliminate cross-CTA launch stalls, which dominate at RecSys's short query lengths and otherwise cost up to two-thirds of compute-intensive net latency. Expressing this in raw CUDA would demand substantial manual orchestration; TLX keeps it concise within Triton's Python programming model and autotuning framework.
IKBO now optimizes Meta's Adaptive Ranking Model on both GPUs and the Meta Training and Inference Accelerator (MTIA). The broader shift is in approach: rather than optimizing around broadcast overhead, we eliminated it at the computational primitive itself, enabling dense interaction quality regardless of candidate count.
LLM Pretraining: Distributed Grouped GEMM
A TLX-based distributed grouped GEMM kernel is deployed in Meta's large-scale LLM pretraining infrastructure, operating continuously across a large GPU fleet for an extended training period. It accelerates the grouped matrix multiplications that mixture-of-experts (MoE) models require and tightly integrates computation with communication to reduce end-to-end latency.
At this scale peak throughput is only part of the equation: reliability, debuggability, and long-term performance stability matter equally, since kernels must hold performance across weeks of continuous operation and stay maintainable as models, hardware, and system software change. TLX fit this environment: warp-specialized execution, explicit memory orchestration, and asynchronous pipelines supplied the needed performance characteristics, while Triton's Python programming model preserved the productivity to iterate, validate, and deploy complex kernels at production velocity. The design philosophy is deliberate — TLX exists not only to hit peak kernel performance, but to make advanced hardware capabilities practical to adopt in real production systems.
Deeper Technical Dives
Companion PyTorch blog posts cover TLX kernels in detail:
- In-Kernel Broadcast Optimization: Co-Designing Kernels for RecSys Inference
- TLX Block Attention: A Warp-Specialized Blackwell Kernel for Fixed-Block Sparse Self-Attention
- Fast 2-Simplicial Attention: Hardware-Efficient Kernels in TLX
- Enabling Cluster Launch Control with TLX
- Achieving Free Normalization: Fusing Norms into GEMM and Attention via TLX
- Optimizing Jagged Flash Attention with TLX: The Road Toward SOTA FA4 on Blackwell
- Optimizing GEMM + Activation on CDNA4 with TLX
Lessons for Compiler Builders
Anchor on Production Workloads
TLX was built to fix real problems at Meta, not to win benchmarks. The GEM MFU and IKBO efforts each started from a concrete pain point (low GEM MFU; RecSys broadcast overhead), and the tooling followed, keeping the work oriented toward real-world performance rather than synthetic scores.
Productivity Compounds Performance
TLX generally matches hand-tuned CUDA performance, but engineers iterate considerably faster. A kernel that is marginally faster yet takes three times as long to write is a net loss at fleet scale. In GEM, the multi-DSL approach let us pick TLX for rapid iteration; in IKBO, the TLX implementation took weeks rather than months.
Accessibility Determines Adoption
WGMMA, TMA, and TMEM are powerful capabilities that saw little use because the programming model was too complex. TLX exposes them through concise annotations, making the IKBO warp-specialized fusion and GEM's multi-DSL kernels feasible where raw CUDA would have been prohibitively complex.
The Compiler Is Part of the User Experience
Error messages, debugging support, and profiling integration matter as much as code-generation quality; we invested as heavily in developer experience as in the optimizer. GEM engineers debugging MFU issues and IKBO engineers hitting warp-group synchronization problems needed clear feedback, not obscure compiler errors.
Evolve Rather Than Replace
Building TLX as a Triton extension let us reuse the existing ecosystem, tooling, and expertise. The GEM team used TLX alongside CUTLASS and CuTeDSL; the IKBO team, already fluent in Triton, had only to learn the TLX annotations for performance-critical sections. A clean-slate design might have been more elegant but might never have shipped.
Roadmap
- More hardware: TLX currently targets NVIDIA Hopper and Blackwell and AMD Mi300 and Mi350x. Work is underway on new NVIDIA and AMD generations and on custom accelerators such as MTIA. The MIMW model itself is hardware-agnostic; the challenge is mapping it efficiently to different ISAs. GEM already runs on GPU and MTIA, and IKBO spans both.
- Higher-level abstractions: TLX gives developers control over warp groups; the next step is inferring warp-group orchestration automatically from higher-level patterns — an "auto-TLX" that writes the annotations. The multi-DSL selection learned in GEM and the three-stage warp specialization in IKBO are candidates for automation.
- PyTorch 2.x integration: TLX is being made a backend for
torch.compile, with the goal of writing PyTorch code and receiving TLX-optimized kernels automatically, no manual annotation needed for common patterns. GEM demonstrates systematic co-design and IKBO demonstrates pattern-specific optimization; both should become automatic.
The missing middle is real, and not only for GPUs. As accelerators grow more complex, programming models must expose the right level of control without sacrificing productivity. TLX is a first step in that direction.