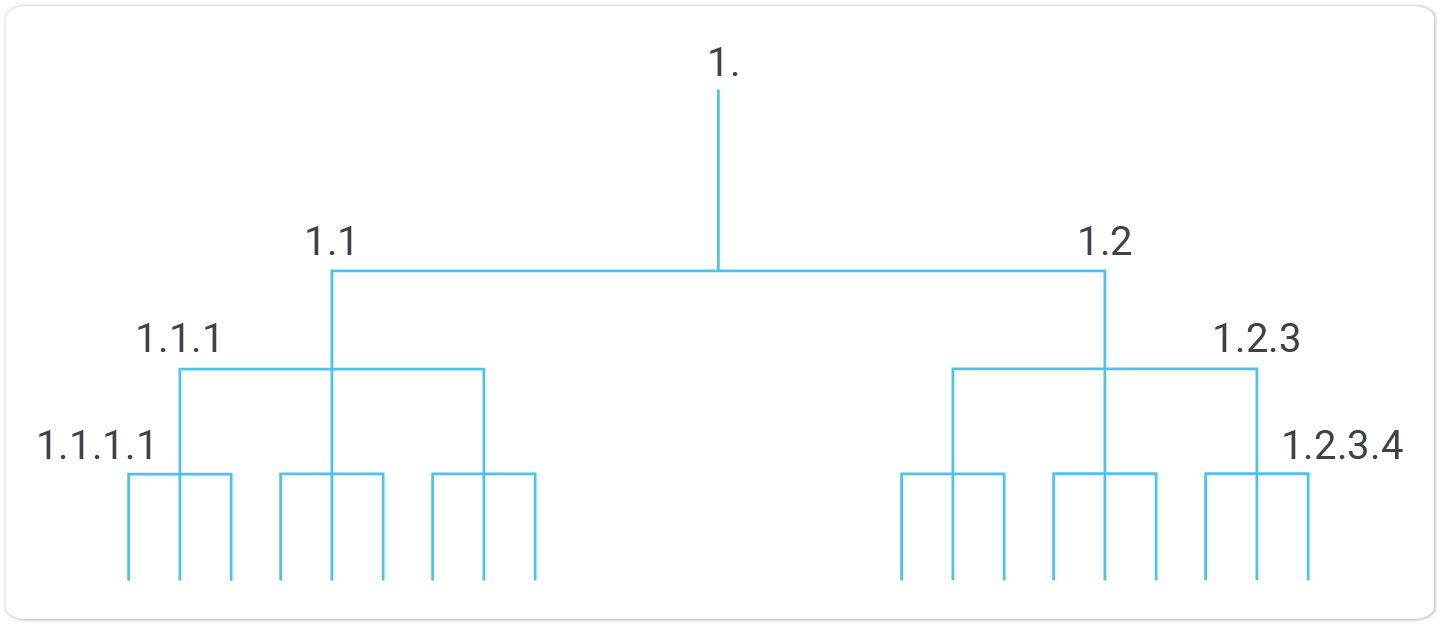
Hierarchical data — org charts, taxonomies, species trees — is supported by all major engines, PostgreSQL included, through recursive queries such as ANSI SQL's WITH RECURSIVE or Oracle's older CONNECT BY. Simple trees are rarely a problem. Once they grow deep and complex, though, the recursive walk starts to cost real time. For trees that stay stable, pre-computation is the cheaper path.
The ltree extension
ltree ships as part of the standard PostgreSQL contrib package, available on most servers, and is present on most cloud services including Amazon RDS, AWS and Microsoft Azure. It provides a data type for representing labels stored in a tree-like hierarchy. Load it with CREATE EXTENSION before use.
The extension deals in labels, not arbitrary strings full of special characters — a point that matters when you start appending path segments.
Storing a hierarchy
The conventional layout is a parent/child pair. A simple structure with a parent_code and child_code column, plus test data, is enough to illustrate:
|
1 2 3 4 5 6 7 8 |
CREATE EXTENSION ltree; CREATE TABLE t_orga ( parent_code text, child_code text, UNIQUE (parent_code, child_code) ); |
Sample rows follow:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 |
INSERT INTO t_orga VALUES (NULL, 'A'), ('A', 'B'), ('B', 'C'), ('B', 'D'), ('D', 'E'), ('C', 'F'), ('C', 'G'), ('E', 'H'), ('F', 'I'), ('I', 'J'), ('G', 'K'), ('K', 'L'), ('L', 'M') ; |
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 |
test=# SELECT * FROM t_orga ; parent_code | child_code -------------+------------ | A A | B B | C B | D D | E C | F C | G E | H F | I I | J G | K K | L L | M (13 rows) |
Here A sits at the top — its parent label is NULL. This much already answers questions like "who works under A → B → C". But when the tree is essentially constant (elephants do not become plants; a rose does not become an animal), the hierarchy can be pre-computed and queried faster.
How ltree behaves
Several small examples show the mechanics:
|
1 2 3 4 5 |
test=# SELECT 'A.B.C'::ltree; ltree ------- A.B.C (1 row) |
|
1 2 3 4 5 |
test=# SELECT ltree_addtext('A.B.C'::ltree, 'D'); ltree_addtext --------------- A.B.C.D (1 row) |
|
1 2 3 4 5 |
test=# SELECT ltree_addtext(NULL::ltree, 'D'); ltree_addtext --------------- (1 row) |
|
1 2 3 4 5 |
test=# SELECT ltree_addtext(''::ltree, 'D'); ltree_addtext --------------- D (1 row) |
An ltree is effectively a dot-separated list. Appending is straightforward, with two catches: appending works when the list contains an empty string, not when it is NULL — a general PostgreSQL behavior worth remembering — and ltree holds labels rather than arbitrary strings, as this demonstrates:
|
1 2 |
test=# SELECT ltree_addtext('A'::ltree, '.'); ERROR: syntax error at position 0 |
Materializing the path
With that in hand, a materialized view can pre-aggregate the hierarchy and store it as its own column, leaving WITH RECURSIVE to do the work:
|
1 2 3 4 5 6 7 8 9 10 11 |
CREATE MATERIALIZED VIEW t_orga_mat AS WITH RECURSIVE x AS ( SELECT *, child_code::ltree AS mypath FROM t_orga WHERE parent_code IS NULL UNION ALL SELECT y.parent_code, y.child_code, ltree_addtext(x.mypath, y.child_code) AS mypath FROM x, t_orga AS y WHERE x.child_code = y.parent_code ) SELECT * FROM x; |
The recursive SELECT has two halves around the UNION ALL. The part before it picks the recursion's starting point — rows where parent_code is NULL, i.e. the top of the tree — and appends a column containing just child_code, since that is the first entry. The part after it joins the result produced so far and extends that trailing column with the current value, repeating until the join returns nothing.
The recursive machinery cannot loop forever unless the data does. Normally you would write UNION instead of UNION ALL to guard against cycles, but that requires the data type to support hashing, which ltree does not. Cycle-freedom must therefore be guaranteed by the dataset itself.
The view yields rows like these:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 |
test=# SELECT * FROM t_orga_mat; parent_code | child_code | mypath -------------+------------+--------------- | A | A A | B | A.B B | C | A.B.C B | D | A.B.D D | E | A.B.D.E C | F | A.B.C.F C | G | A.B.C.G E | H | A.B.D.E.H F | I | A.B.C.F.I G | K | A.B.C.G.K I | J | A.B.C.F.I.J K | L | A.B.C.G.K.L L | M | A.B.C.G.K.L.M (13 rows) |
The final column carries every level above. Querying it for everyone under A → B → C → G looks like this:
|
1 2 3 4 5 6 7 8 |
test=# SELECT * FROM t_orga_mat WHERE 'A.B.C.G' @> mypath; parent_code | child_code | mypath -------------+------------+--------------- C | G | A.B.C.G G | K | A.B.C.G.K K | L | A.B.C.G.K.L L | M | A.B.C.G.K.L.M (4 rows) |
Many more operators exist and are documented in the official ltree reference.
Making the index get used
On a small table PostgreSQL will prefer a sequential scan and ignore the index. To force the optimizer's hand, make sequential scans prohibitively expensive:
|
1 2 3 4 5 6 7 8 |
test=# SET enable_seqscan TO off; SET test=# explain SELECT * FROM t_orga_mat WHERE 'A.B.C.G' @> mypath; QUERY PLAN --------------------------------------------------------------------------- Index Scan using idx_mat on t_orga_mat (cost=0.13..8.15 rows=1 width=96) Index Cond: (mypath <@ 'A.B.C.G'::ltree) (2 rows) |
With that setting, the plan uses the intended index:
Related reading
Hierarchical data has come up here before — see the earlier post on WITH RECURSIVE and company organization.