

The October write outages exposed an unsafe interaction between database orchestration and production routing. An October 29 Azure network disruption affected all three Central US availability zones and at least 34,128 signed-in users.
Capacity and reliability work
As of November 9, 140 of 151 production services and 32 of 50 MySQL primaries were running in Azure Central US. Azure served 63% of migrated-service reads, 66% of monolith reads, and 52% of Git reads. We also completed a compute expansion across all nine Central US Kubernetes clusters, more than doubling capacity.
That capacity is already carrying real growth. Migrated-service traffic has increased 82% since March, with Central US absorbing the growth beyond the highest weekly-average load previously served from our existing datacenter. This gives GitHub more room to grow without pushing the original environment beyond its prior operating range.
We also made several targeted reliability improvements. Actions changes increased capacity for critical Azure control-plane requests. A separate NAT-gateway mitigation reduced usage by 85%; four production jobs failed during the change, compared with approximately 800 expected without the mitigation. Connection limits and other client improvements now also reduce the chance that a dependency interruption becomes a broader reconnect storm.
We removed concentrated sources of database load as well. A high-traffic GitHub Actions endpoint handling more than 250 million requests per day moved to a more efficient service path, reducing peak database reads by 85%. Requiring at least three characters before searching repository topics reduced slow or terminated queries for that pattern by approximately 98%.
The East US 3 buildout is about one week behind plan. The next phase starts with its first validated traffic ramp in the first week of December, while we continue hardening migration safety, dependency isolation, and regional recovery.
October 05: Actions job assignment failure
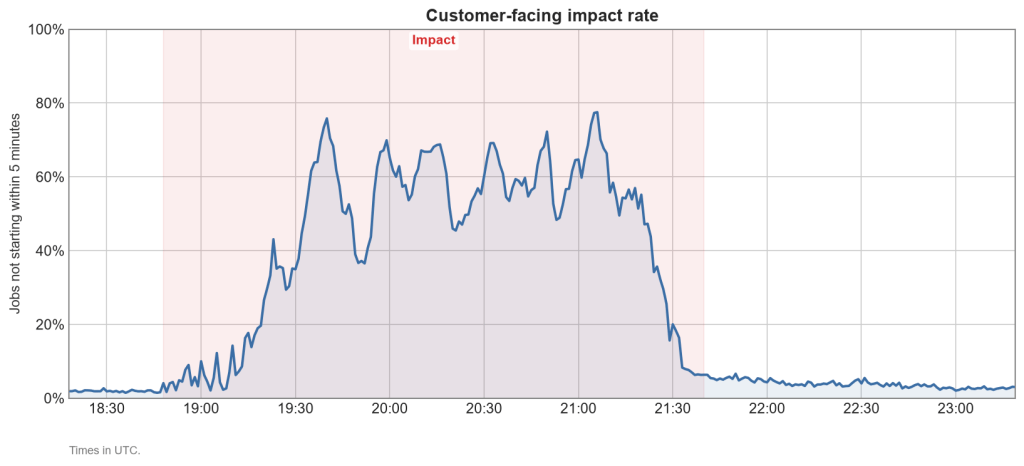
Jobs on GitHub-hosted runners stayed queued or failed to start. During the worst stretch, which lasted about 90 minutes, most jobs on GitHub-hosted runners did not start within five minutes. Self-hosted runners were not affected, and GitHub Pages sites that build with actions were slow to update, though existing sites continued to serve normally. Some repository lists, licensing and billing pages, and some Copilot features returned errors.
A partial networking failure on our cloud provider's side disrupted some of the connections between one of our datacenter regions and the cloud-hosted databases that the job-assignment service depends on. Instead of failing fast, the service waited for those calls to time out, and the waiting calls piled up until it ran out of memory and restarted. Jobs then shifted to the same service in a healthy region, which lacked capacity for the extra demand and began failing too. Runners that went several minutes without receiving a job shut down and were slow to be replaced.
We redeployed the assignment service without recovery and traced the failures to the networking issue. We failed over the affected databases and storage to healthy regions one service at a time and added capacity; some services kept failing even after failover and recovered only once the provider resolved the networking failure.
Follow-up work covers four areas:
- Making the assignment service better able to handle sudden load increases when another region shifts extra jobs to it.
- Prioritizing runner assignment based on customer profile when available runner capacity is degraded.
- Changing GitHub-hosted runner behavior to reduce recovery time when job assignment services are degraded.
- Improving how quickly we detect and locate partial network failures between our datacenters and the cloud-hosted services they depend on.
October 06: Enterprise Importer overloads a shared database
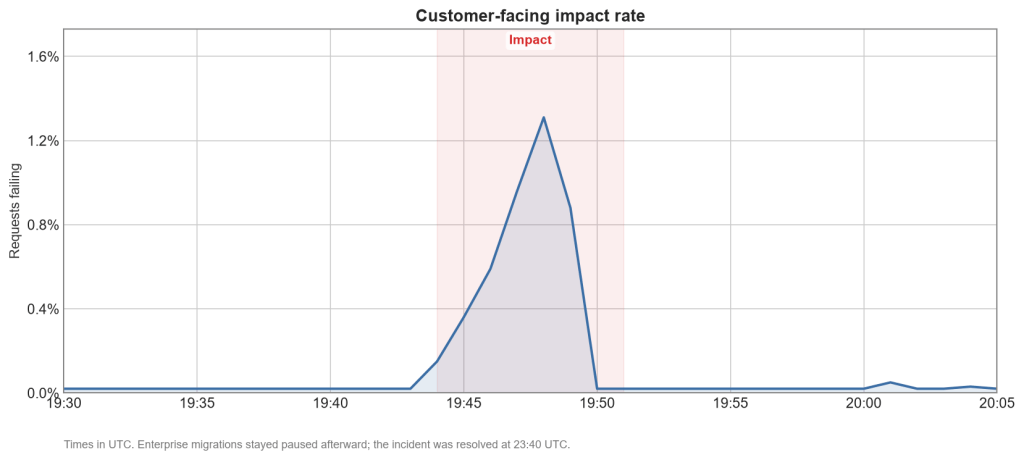
About 1.3% of all requests failed or timed out at peak, and about 6.4K organizations saw at least one failed or slow request. Signing in, working with repositories and pull requests, calling the API, and GitHub Codespaces were among the affected surfaces. Retrying shortly after succeeded, and delayed webhook deliveries caught up soon after.
A surge in migration activity caused GitHub Enterprise Importer to send a burst of very large queries to a shared database. Together with normal traffic, these queries used all of the database's connections, blocking other github.com features that rely on the same database. The importer did not reduce its load when the database became overloaded. Impact ended within minutes, once the importer finished its queued queries and connections were released. We paused migrations until a mitigation that runs these queries in smaller batches was deployed, then resumed them.
We optimized the query the importer sends so each one stays small and fixed in size, and we are automating importer backoff under database strain. Database alerts that flag queries doing much more work than usual — and identify the responsible query — are also being added.
October 07: Two write outages from bad routing settings
Two separate write outages totaled about 19 minutes, and the second recurred with the same cause. Web and API request failures peaked at 8.9% in the first outage and 9.3% in the second, affecting more than 12,000 and more than 11,000 organizations respectively; some organizations may have been hit by both. Pushing code, signing in, updating pull requests or issues, and API changes failed. Webhooks, GitHub Apps and OAuth, actions, code scanning, codespaces, and Copilot were also affected, while viewing content was largely unaffected. Saved data was not lost, and failed actions succeeded when retried after recovery.
During regular maintenance, we replaced machines that manage where database writes are sent. One new machine started with outdated records that still listed retired database servers. Once automatically elected leader, it published routing settings that sent writes for several core databases to those retired servers. Incorrect settings passed existing validation and took effect immediately. A later automated maintenance task did not honor a pause on maintenance and triggered another election, and the new machine, not yet removed, became leader again.
Writes recovered each time an established machine with correct records became leader. After the first incident we paused automated maintenance, which the subsequent task ignored. We then removed the new machine and resolved the second incident.
Remediation: improved retirement of database servers so outdated records aren't left behind; tighter controls on adding new machines that manage database routing, including ensuring automated maintenance honors a pause; and stronger validation of routing settings so incorrect ones are caught before taking effect.
October 19: Actions cache retries saturate a network link
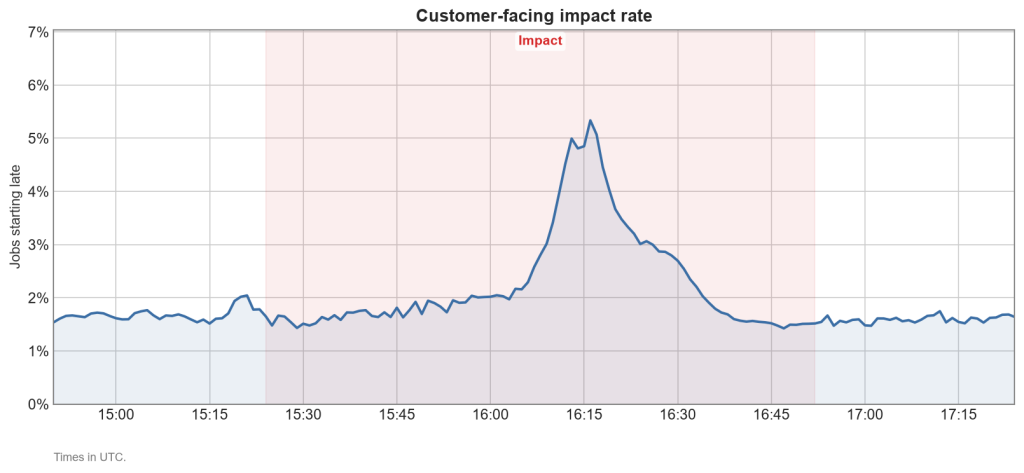
About 5% of jobs on GitHub-hosted runners experienced delayed starts, a very small share of workflow runs failed, and some requests to the actions jobs REST API returned errors. Workflow status updates, logs, checks, GitHub Pages deployments, and workflow and check webhook events from actions runs were delayed; for part of the time, live updates on github.com and code search were degraded.
An internal actions service that stores workflow logs and run status lost connections to some of its cache servers in one cloud region, and every server running the service retried at the same time. The combined retries saturated the network connections between GitHub's data center and that region, disrupting other services on the same link. We routed the service away from some cache servers in the region — the link stayed over capacity — then away from the rest, after which it recovered. Processing limits were raised to clear the actions backlog.
We have limited how quickly this service can open new connections to its cache servers, and we are alerting on spikes in new connections from it to identify the source sooner.
October 21: event streaming memory pressure and a spreading broker overload
This incident ran from 14:52 UTC and lasted 4 hours and 30 minutes; the total duration was approximately 6 hours and 46 minutes. Pull request updates, GitHub Actions workflow status updates and webhook deliveries were delayed. New commits were slow to show up on pull requests after a push, workflows triggered by that push started late, and status checks from Actions workflows could appear stuck, blocking merges that require those checks. These features recovered within about 2 to 3.5 hours.
Audit logs lagged longest: recent activity took up to 1 hour and 50 minutes to appear in searches, and the events were fully caught up after roughly 6 hours and 46 minutes. Some webhook deliveries from the window may be absent from webhook delivery history even though the webhooks were delivered.
The root cause was memory pressure in the event streaming platform. Memory use on these servers scales with the number of client connections, and some were close to their limits. When requests failed, clients opened new connections immediately, pushing connection counts and memory use higher, which slowed and then overloaded the servers. Taking the overloaded servers out of service shifted traffic to others, which became overloaded in turn over the following hour. Rebalancing overloaded partitions onto brokers with spare capacity mitigated the problem.
Audit logs were slowest because the service writing audit log events restarted repeatedly on platform errors for more than two hours, falling further behind. Once stable, it could write events only at a limited rate, so the backlog took several more hours to drain.
- An incident was declared and some traffic was moved off an overloaded server, but more servers soon followed.
- The busiest traffic was split into more partitions and moved to less-loaded servers; every affected feature except audit logs recovered gradually.
- After the audit log service stopped restarting, its write rate was raised to clear the backlog faster.
- The incident was resolved once audit log delays were back in the healthy range, with the remaining backlog cleared afterward.
Follow-up work includes randomized delays on reconnects after failed requests, so already-slow servers do not receive a burst of new connections; earlier alerting on server memory use; a second switchable destination for webhook delivery data to keep deliveries moving if the streaming platform slows; and improved playbooks for moving hot partitions.
October 28: an invalid upstream credential broke Copilot model requests
This incident began at 14:12 UTC, lasted 1 hour and 16 minutes, and had a total duration of approximately 1 hour and 32 minutes. Requests to several GPT-family models in Copilot failed or did not complete across Copilot Chat in IDEs and on github.com, the Copilot CLI, Copilot code review and the Copilot coding agent. About one in 10 requests to the affected models failed, while other models kept working; selecting another model avoided the errors, and auto model selection reduced them by routing some requests elsewhere. Code scanning autofix and code quality, which depend on one specific model with no fallback, were hit harder.
The failure came from the credential Copilot uses to authenticate with an upstream model provider. It became invalid, the provider rejected requests as unauthenticated, and the rejections surfaced to clients as authentication errors. Every Copilot feature routed through that provider failed at the same time.
- Alerts flagged rising errors on the affected models and an incident was declared.
- A public status update recommended using another model in the interim.
- The errors were traced to the credential, and a replacement was created.
- Requests recovered as the new credential was deployed to the first environment, then to the rest.
- The incident was resolved after confirming that requests to the affected models had recovered.
Remediation covers retrying requests instead of failing when an upstream provider reports authentication failure, stronger credential management for upstream model providers, and alerts on upstream authentication failures.
October 30: connection pool exhaustion on github.com
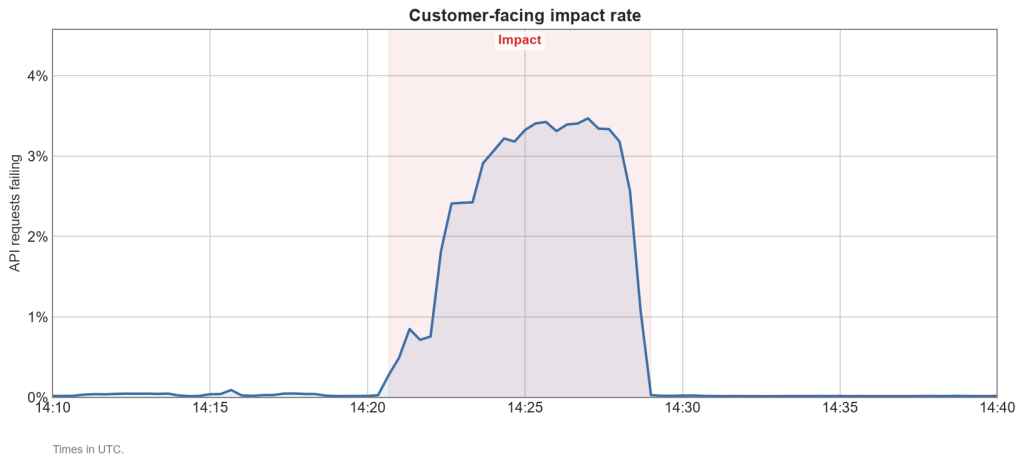
The window began at 14:31 UTC and lasted 31 minutes, with a total duration of approximately 9 minutes. Some requests to github.com hung for up to about 10 seconds before failing with a server error. Pull request merges and Git operations over SSH and Git LFS were worst affected: at peak, about 43% of merge attempts failed, against about 3.5% of API calls. Issues, GitHub Pages, notifications, and sign-in for GitHub Apps and OAuth apps also showed intermittent errors.
A shared database connection pool used by many github.com services hit its limit, and for several minutes no connections were available; new requests waited out the connection timeout and then failed. The pool was already near capacity when some update requests began holding connections far longer than expected: each wrote a change and then ran a separate lookup that could take several seconds, keeping its connection reserved but idle. With little headroom, those held connections tipped the pool over.
- Requests exhausted the shared pool and failures spread across github.com.
- An incident was declared and on-call engineers for affected services were paged.
- Error rates returned to normal as the pool drained; a public status update followed confirmation of the cause.
- The incident was resolved after verifying connection levels and monitoring for stability.
Changes include running the slow lookup before these updates begin writing, so no connection is held while it waits, and evaluating limits on how long a pooled connection may be held to contain similar slow request patterns.


