This edition of the availability report covers two months rather than one: no September update was published while separate public content addressed the August 17 outage.
Overall, the period brought reduced shared-database pressure, new overload controls, more headroom for GitHub Actions, broader failure containment for pull requests, and more production workloads running in Azure. It also brought significant incidents, a capacity pause and a missed migration target — evidence that the work is unfinished.
The guiding principle is unchanged: availability, then capacity, then features.
Migration to Central US: progress, a pause and one failure mode
As of October 7, 120 of 160 production services were running in Central US, and 13 of 51 primary MySQL databases had been moved. The region also absorbed 65.4% of read traffic for GitHub's core application, 48.3% of Git read traffic and 80.2% of stream-processing traffic. Because these figures cover different workloads, they cannot be summed.
Deployments to Central US and traffic increases were halted on September 11 after capacity proved uneven across availability zones. Temporary relief allowed permanent ramps to restart on September 18, though durable capacity work is still underway, targeting all available capacity by the end of October. The aggressive September 30 goal of deploying every production service to the region was not met.
A planned database failover exposed another problem: an automated emergency process disconnected Central US database copies and disrupted customers in that region. The process has been disabled during planned handoffs while recovery behavior is improved.
Shared-database load and pull request containment
Work outside the regional migration targeted the oldest shared database: 24 authentication-core tables were moved off it, removing roughly one million queries per second from its replicas. On the cluster behind issues and pull requests, about 980 million unnecessary edit-history rows were deleted, an estimated 1.8 terabytes of recoverable storage. Weekly deadlocks dropped approximately 77% from their June peak, and continuous cleanup keeps that growth from returning.
Half of sampled pull request traffic can now keep working with limited functionality when a shared dependency fails, and production results showed several read operations remaining available during a shared-database incident. Database traffic routing can add capacity automatically during spikes — one group went from 14 to 19 instances during a September 23 rise in pull request activity. A production overload control lets responders shield higher-priority API and web workflows by rejecting lower-priority requests before saturation spreads. Operator documentation and training are complete.
Actions: measured headroom
Production changes to GitHub Actions cut measured Redis operations by about 28% and relative CPU by about 30%. A separate infrastructure cache reduced Redis bandwidth by 84%, average response time by 66%, median response time for the primary inventory request by 96%, and queued requests by 95%.
The August 6 Actions outage, the August 17 github.com outage, the September failover disruption and the controlled capacity pause all make the same point: improvements only count when they lower customer risk under real conditions.
September 13 09:16 UTC (1 hour 28 minutes)
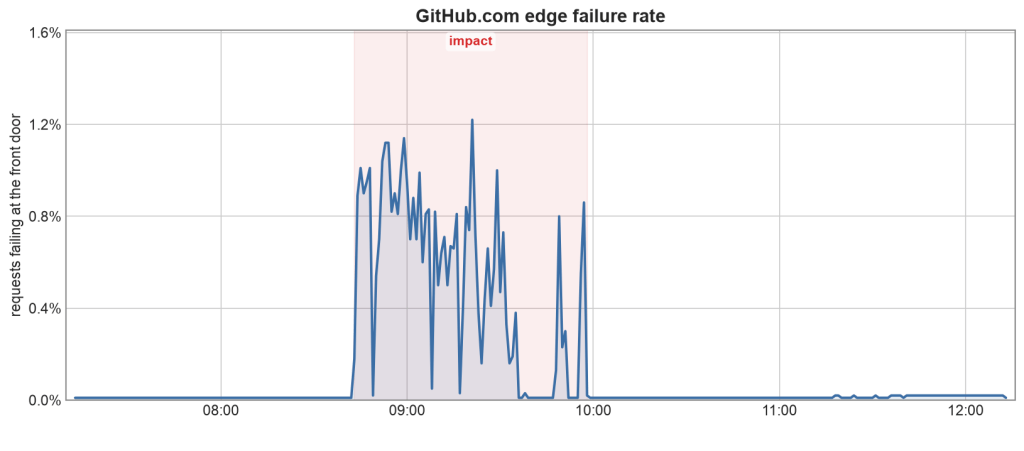
What went wrong. A background data-cleanup job added load to a shared database. Its safeguard was built to slow writes when replicas fell behind, but it ignored incoming load on the primary server, so the job kept writing until the primary hit its connection limit. Requests depending on that primary could no longer complete reliably.
Two further factors widened the impact and slowed recovery. Database calls had no quick timeout, so handlers waited on the stalled database instead of failing fast. And a retry loop around token creation kept re-sending writes that were already failing, holding the database at saturation instead of letting it recover.
Response sequence.
- The background cleanup job began writing to the shared database.
- Its safeguard monitored replica lag only, missing the load accumulating on the primary.
- The primary exhausted its connections; dependent services failed or slowed.
- Automated monitoring fired and failures were traced to shared-database load.
- Internal load was reduced and the background job paused.
- The database recovered and error rates returned to normal.
Follow-up. Additional safeguards will control background processing against available database capacity, cut unnecessary retries during failures and limit the blast radius of slow database requests. Service startup behavior is also being changed so brief database connectivity problems do not needlessly interfere with recovery.
September 28 21:16 UTC (52 minutes)
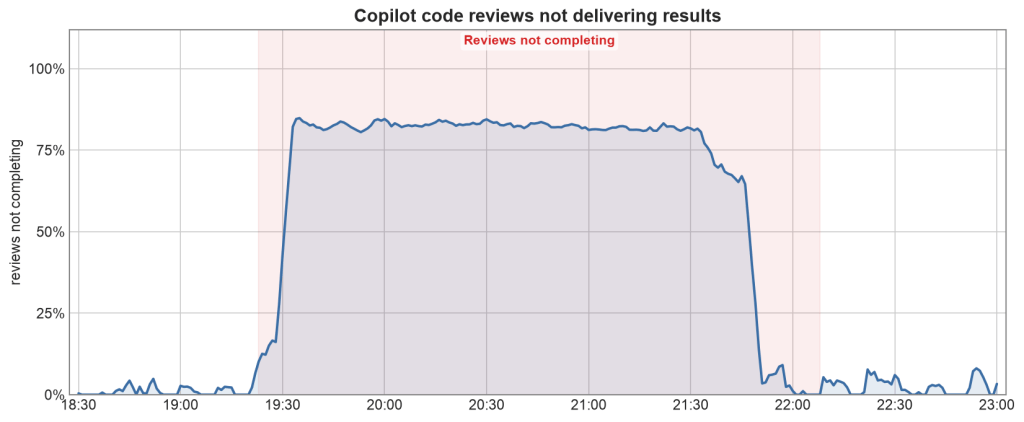
What went wrong. Copilot code review runs reviews through a separate service that returns two versions of the results: a limited copy without review comments and a full copy that includes the completed review. Only the full copy is used to post reviews. A change to that service started sending the full copy for just some customers, leaving others with the limited copy alone.
Copilot code review therefore could not assemble a review while still reporting the job as successfully completed, and the missing results went unnoticed because monitoring did not cover them. The incident surfaced when some reviews stayed incomplete past 30 minutes triggereding an alert to first responders. Reverting the change mitigated it.
Response sequence.
- A rollout to the review-running service began; review results stopped appearing on pull requests, and the change reached every environment.
- Reviews started timing out and alerted the Copilot code review team, which declared an incident.
- Failures were traced to the change and the revert began.
- While the revert cleared its required checks, the incident was posted to the GitHub Status page.
- The revert reached all affected regions; the incident was resolved and customers were advised to request affected reviews again.
Follow-up. Safeguards are being added across the review and delivery path so completed reviews are delivered, failed reviews recover automatically and issues are flagged earlier. Monitoring and deployment processes are being improved so problems are found and fixed faster.