Two autoscalers, one target
Netflix runs two Flink autoscalers in production: one built in-house when no mature alternative suited its platform, and one derived from the Apache Flink community that can scale workloads the homegrown system was never designed for. The company is steadily converging on the open-source version.
Stream processing on Apache Flink dates back to 2017 at Netflix; as of 2026 the fleet exceeds 30,000 jobs across multiple AWS regions. Most are generated by the managed Data Mesh platform, so their users never touch a Flink job directly. A smaller, growing set are custom jobs for personalization, Ads, and Live events — from single-operator Kafka-to-Kafka shuttles to stateful pipelines with branches, joins, and terabytes of state, with load that swings on daily cycles, launches, and regional failovers.
Provisioning for peak wastes capacity; provisioning for the average causes lag. And scaling is not free: by default it means taking a savepoint, stopping the job gracefully, and restarting it at the new size, which for a large stateful job can take minutes.
The homegrown scaler: coarse metrics, one knob
The first autoscaler, built around 2019, was itself shaped like a stream-processing job. It ran on Mantis, consuming a live feed of cluster-level metrics from Atlas — CPU, network, Kafka lag, input-rate, and consume-rate signals per job. Decisions combined lag-derived catch-up time, CPU/network utilization thresholds, observed performance history, and regression over recent input rate. Because it lives outside the Flink platform, it stays unaffected by problems inside Flink, and because it is a streaming job, it scales easily: each autoscaler node handled a subset of jobs with no custom sharding or coordination. It reliably cut resource usage by 25–45% across thousands of managed pipelines.
Its ceiling is the outside view. It reasoned about a whole cluster through coarse container metrics and scaled a single knob — total TaskManager count — so every operator moved together. That fit the simple pipelines it was built for, not the multi-operator DAGs teams brought for Ads, recommendations, and games; each new case meant more custom logic rather than general capability. It is also only as good as the metrics beneath it. A job could be busy without that showing as CPU utilization, leaving it degraded where the scaler could not see. Later, a networking migration changed how some traffic was reported and a subset of the Atlas metrics stopped capturing everything accurately — a gap that stayed invisible until it surfaced in production.
How the OSS autoscaler reasons
The community option is the Apache Flink Autoscaler, which reasons from inside the job rather than watching containers.
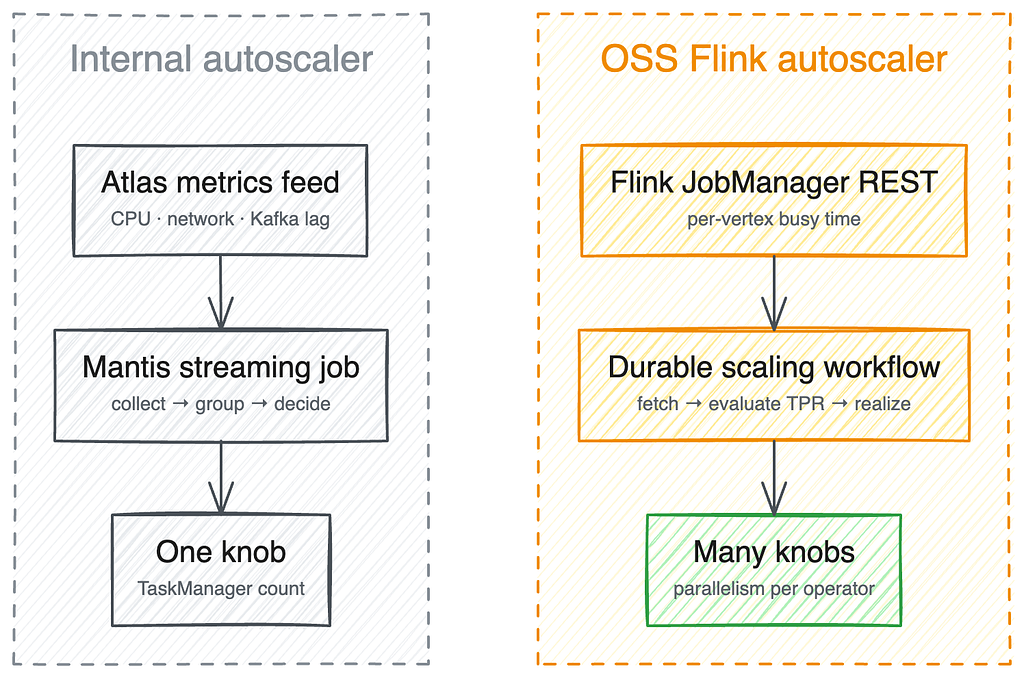
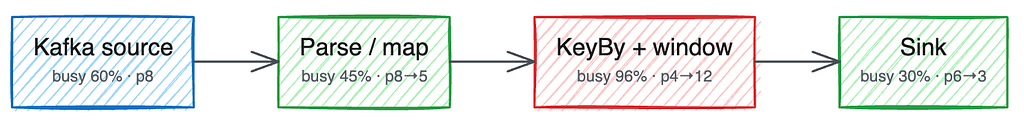
It estimates each operator's true processing rate (TPR) — the throughput it could sustain if fully busy. Flink reports, per subtask, the fraction of each second spent doing work, separate from time backpressured or idle. Dividing observed throughput by that busy fraction extrapolates to full utilization: 700 records/sec at 70% busy implies a TPR of 700 / 0.7 = 1,000 records/sec. Starting from the sources, the autoscaler walks the job graph and uses each operator's TPR, input/output ratios, and a target utilization to compute the parallelism every vertex needs so no operator becomes the bottleneck, instead of resizing the cluster as a unit.
The two systems make different contracts.
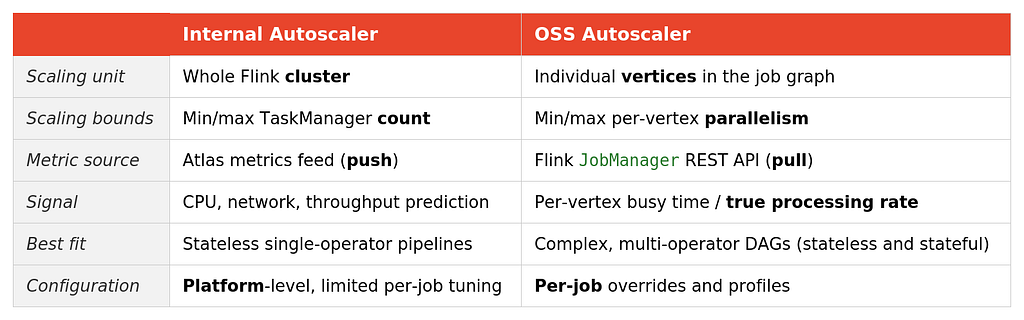
The decisive rows are the last two: the OSS autoscaler scales exactly the stateful, multi-operator jobs the homegrown one could not, and each job carries its own configuration — stabilization periods, thresholds, and other behavior. That suited the custom jobs teams had been scaling by hand.
Running it outside the Kubernetes Operator
The algorithm was the community's hard part. The work was running it reliably across Netflix jobs, which is where the deployment diverges from stock.
The OSS autoscaler was originally architected inside the Kubernetes Operator for Flink, but Netflix's Flink platform runs on its own control plane. The community kept the core logic as a standalone library and refactored four generic interfaces that plug into an internal ecosystem: a context carrying job metadata and REST API info, a state store, an event handler, and a realizer that applies scaling decisions.
The resulting service is a Spring Boot application orchestrated on Temporal. An orchestrator workflow polls the Flink control plane about once a minute for jobs with autoscaling enabled, then starts one long-running workflow per job. Each per-job workflow pulls per-vertex metrics from its Flink JobManager, runs the OSS evaluation algorithm, and passes any scaling decision to a realizer that actuates the change through the Netflix control plane.
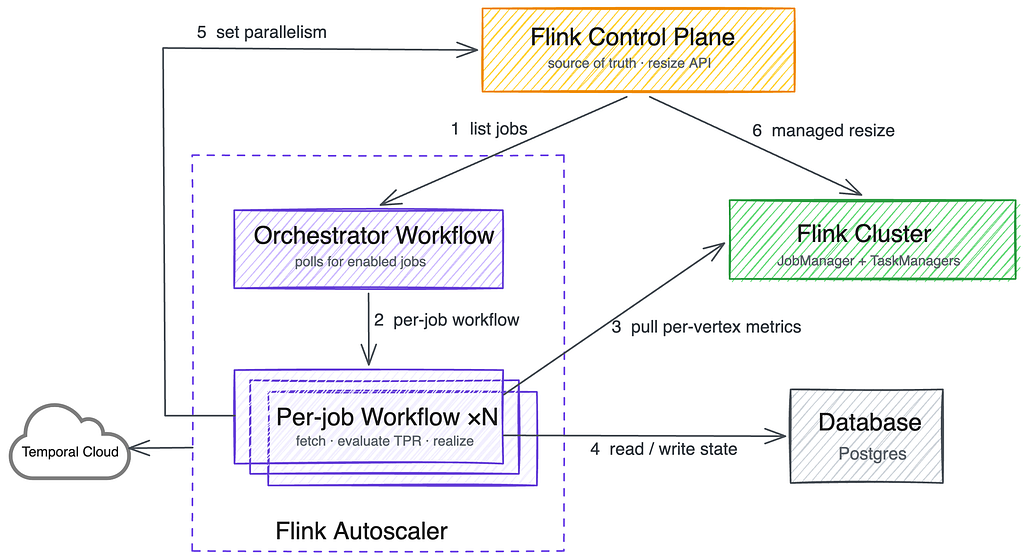
The workflow-per-job design answered a concrete failure. Running evaluations in a single batch loop was fragile: one slow job could stall metric collection and scaling for everything behind it. Per-job durable workflows isolate that blast radius, so a problematic job fails and retries alone, and the runtime scales out as more jobs are onboarded.
Three gaps stood between community-ready and Netflix-scale:
- Metric collection at high parallelism. On big jobs, pulling metrics from the JobManager became a bottleneck, partly due to Flink's runtime. The JobManager was changed to cache transient metric names and clean them up once instead of rescanning on every fetch, plus server-side filtering so the autoscaler requests only the metrics it needs. The autoscaler now works on jobs up to 3,000 Flink subtasks, where it previously struggled above roughly 1,000. Some changes sit in an internal Flink fork; others are contributed upstream, such as FLINK-36172.
- Preserving forward chaining. Two vertices joined by a forward connection must run at the same parallelism, since records move in memory on a fixed local channel. Scaling one alone does not fail — Flink silently converts the edge into a network shuffle. The fork detects forward-connected subgraphs and scales each as a unit.
- Respecting sink limits. Some sinks have finite write capacity, so async-sink backpressure detection (also a fork change) keeps the autoscaler from scaling into a sink that cannot absorb more.
Before actuating, the realizer runs safety checks: it refuses to scale down in a region being evacuated during a company-wide failover, verifies enough disk for the new cluster to hold the job's checkpoint state, and adds a small standby buffer for larger clusters.
Results, tuning, and the recovery bottleneck
The OSS-based autoscaler reached general availability for custom jobs last year with promising early outcomes. The client telemetry and logging team saw a 58% reduction in annualized Flink compute expenditures, roughly $1.1 million annually. Three factors drive it: autoscaling tracks daily cycles that static provisioning cannot, capturing the drop at nights and weekends; capacity is adjusted continuously instead of relying on manual optimization after performance improvements or holiday slowdowns; and uniform container dimensions allow better bin-packing and finer scaling increments.
Scaling down too eagerly is its own trap. Cut too deep and CPU saturates with lag spikes, and the system cannot react immediately because the metric window and stabilization period rebuild after each restart. Netflix runs a target utilization of 0.45, below the community default of 0.7, trading a little efficiency for stability — fewer, calmer rescales are worth the marginal cost on large stateful jobs.
Fine-grained signals and vertex-level decisions do not remove the real cost of a rescale: restart and state recovery, which depends on Flink Core's state restoration performance. Flink 2 addresses this via disaggregated state, keeping state in external storage rather than local disk to sharply reduce dependence on total state size. Netflix already supports Flink 2.2 and plans to experiment with the new state backend on large stateful jobs.
The goal ahead is migrating all internal scaler use cases onto the OSS-based autoscaler to simplify the operational surface area.
Lessons
- Metric choice matters more than algorithm sophistication. The most useful debugging was rarely about scaling math; it was about which signal to trust. Understand metrics before tuning the algorithm.
- Set sensible defaults, but leave room to tune. One good default covers most managed jobs, which is the point of a platform, but forcing a single configuration punishes jobs that do not fit. Netflix pairs defaults with per-job overrides and hides knobs that need deep expertise.
- Adopt, then extend. In-house was right in 2019 when nothing mature fit. When a strong community project appeared, the right move was neither defending the investment forever nor ripping it out overnight, but adopting it for new workloads, contributing fixes back, and migrating deliberately.