Interactive applications that present large result sets rarely show them all at once. Splitting the output into pages is second nature to anyone who has used a web search: you get a page of rows, a control for the next page, and a total result count. The pagination itself can be done in several ways with very different performance characteristics. The result count is a separate and much harder problem.
Setting up the example
To compare the techniques, we build a table and load it with time series data:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 |
CREATE UNLOGGED TABLE data ( id bigint GENERATED ALWAYS AS IDENTITY, value double precision NOT NULL, created timestamp with time zone NOT NULL ); /* make the example repeatable */ SELECT setseed(0.2740184); INSERT INTO data (value, created) SELECT random() * 1000, d FROM generate_series( TIMESTAMP '2022-01-01 00:00:00 UTC', TIMESTAMP '2022-12-31 00:00:00 UTC', INTERVAL '1 second' ) AS d(d); /* add a primary key */ ALTER TABLE data ADD PRIMARY KEY (id); /* set hint bits, create visibility map, gather statistics */ VACUUM (ANALYZE) data; |
The query under test:
|
1 2 3 4 |
SELECT value, created FROM data WHERE value BETWEEN 0 AND 10 ORDER BY created; |
A two-column index serves this query best, because it lets PostgreSQL perform an index-only scan that also satisfies the ORDER BY clause:
|
1 2 |
CREATE INDEX data_created_value_idx ON data (created, value); |
That index accelerates the first rows, and it is equally the best choice for reading the entire result set.
OFFSET and LIMIT
The classic approach fetches chunks of 50 rows by skipping everything before the current page:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 |
/* the first page */ SELECT value, created FROM data WHERE value BETWEEN 0 AND 10 ORDER BY created LIMIT 50; /* page number 100 */ SELECT value, created FROM data WHERE value BETWEEN 0 AND 10 ORDER BY created OFFSET 4950 LIMIT 50; |
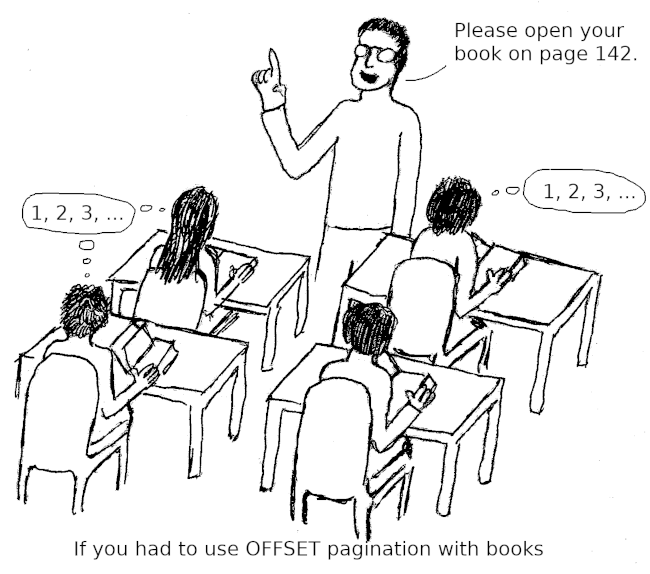
The drawbacks are well known and twofold. First, performance degrades the further you page in: to produce page 100, PostgreSQL must compute the first 5000 rows and throw away 4950 of them. All that work is wasted, and it grows with every page. Applications where users never look past the first few results can live with this. Second, concurrent writes break the illusion of a stable result set. A row inserted while the user views page one can shift the whole ordering, so page two starts with the last row of page one. A concurrent delete can cause a row to be skipped entirely when the user moves to the next page.
The compensating virtue is simplicity: it works with any query, and it performs acceptably as long as only the first few pages are requested.
Cursors, WITH HOLD and otherwise
Fetching a result set in chunks is what cursors are for. An ordinary cursor is bound to a transaction, which rules it out for pagination driven by user interaction: a long-lived transaction holds table locks that can block DDL or TRUNCATE, and it stalls autovacuum, inviting table bloat.
A WITH HOLD cursor escapes that limitation. At the end of the transaction it fetches the complete result set and materializes it on the server:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 |
START TRANSACTION; /* * Don't use SCROLL unless you need to scroll backwards, * for example to get the total count (see below). */ DECLARE c SCROLL CURSOR WITH HOLD FOR SELECT value, created FROM data WHERE value BETWEEN 0 AND 10 ORDER BY created; /* this will calculate the whole result set */ COMMIT; |
Any page can then be read at will:
|
1 2 3 |
/* get page number 100 */ MOVE ABSOLUTE 4950 IN c; FETCH 50 FROM c; |
The cursor must be closed when it is no longer needed:
|
1 |
CLOSE c; |
Fetching the first page before the transaction commits is worthwhile, because the COMMIT that materializes the result set can take a long time; the client can render page one while that happens.
Its strengths: it works with all queries, the result set is stable so rows are neither skipped nor repeated as with OFFSET, and it is probably the best fit when the whole result set will eventually be retrieved or the total count is needed, since everything is computed anyway. Its weaknesses: forgetting to close the cursor keeps the result set on the server until the session ends; transaction-level connection pooling does not work with WITH HOLD cursors because they are tied to a database connection; the whole result set is computed when the initial transaction ends, so the first page can be slow even though later pages are fast; and a cursor held open for a long time yields stale results.
Keyset pagination
The most advanced variant relies on the values of the ordering columns rather than on a row count. It requires fetching the id column as well:
|
1 2 3 4 5 |
SELECT id, value, created FROM data WHERE value BETWEEN 0 AND 10 ORDER BY created, id LIMIT 50; |
After reading a page, we remember id and created from its last row and use them to request the next one:
|
1 2 3 4 5 6 |
SELECT id, value, created FROM data WHERE value BETWEEN 0 AND 10 AND (created, id) > ('2022-01-01 01:27:35+01', 5256) ORDER BY created, id LIMIT 50; |
Here 2022-01-01 01:27:35+01 and 5256 are the remembered values. The id column acts as a tie-breaker when several rows share the same created timestamp.
Efficiency for the second WHERE condition demands a dedicated index:
|
1 2 |
CREATE INDEX data_keyset_idx ON data (created, id, value); |
Including value in the index is not necessary for speed; it is there to enable an index-only scan so that the comparison with the other methods is apples to apples.
The advantages: each query touches only the portion of the result set it needs, which beats the other techniques; rows are never skipped or repeated as with OFFSET; and every query returns current data, reflecting the latest concurrent modifications.
The disadvantages: it needs a special index tailored to the query, and it is only applicable when the exact query is known in advance.
Measured performance
Measurements were taken for the example above, reading response time on the client side over a local connection and averaging five runs, with EXPLAIN (ANALYZE, BUFFERS) used to count the buffers processed. All data was cached in shared buffers and random_page_cost was 1.1.
| page 1 | page 10 | page 100 | |
|---|---|---|---|
OFFSET/LIMIT |
1.16 ms 25 buffers |
4.42 ms 184 buffers |
15.36 ms 1915 buffers |
WITH HOLD cursor |
642.28 ms (1.41 ms without COMMIT)120507 buffers |
0.34 ms
0 buffers |
0.51 ms
0 buffers |
| keyset pagination | 1.40 ms 30 buffers |
1.35 ms 31 buffers |
1.39 ms 24 buffers |
For the first page, OFFSET and LIMIT comes out ahead, possibly because it fetches one column less. Once more pages are needed, keyset pagination wins. Cursor pagination competes only if the COMMIT happens asynchronously while the user is looking at page one; for subsequent pages, however, it is the fastest of the three, because the result set has already been calculated.
Counting the whole result set
Clever pagination does not extend to the total count. There is no shortcut: the complete result set must be computed and then counted. How much that hurts depends on the pagination method.
- With
OFFSETor keyset pagination, it means an additional expensive query. When only the first few pages are read, that counting query usually costs more than all the page queries combined. - With
WITH HOLDcursors, the whole result set has already been materialized, so the count comes for free:PgSQL
1
2
/* the result will be 'MOVE 314711' */
MOVE ALL IN c;
Either way, computing the complete result set is slow, and count(*) queries for pagination counts frequently turn out to be the most expensive part of an application's workload. The practical guidance follows from that:
- Simplest of all: do not show a count. Google does not display exact counts either.
- Failing that, show an approximate count. Run
EXPLAIN (FORMAT JSON) SELECT 1 FROM /* your query */instead ofSELECT count(*) FROM /* your query */and pull the row estimate out of theEXPLAINoutput. - If an exact count is genuinely required, do not show it up front. Put it behind an initially disabled option, such as a “get exact count” button, so the user pays the price only when he or she chooses to.
- Whatever the approach, compute or estimate the count only when the first page is displayed. Never re-run it for each page the user requests.
Summary
OFFSET/LIMIT, WITH HOLD cursors and keyset pagination each have their own trade-offs, and the choice depends on the situation. A displayed total result count, on the other hand, is expensive under all of them, so it is best avoided wherever possible.