The Netflix homepage is a structured, two-dimensional layout: multiple recommendation rows, each containing entities such as movies, shows, games, or live events. Building it has traditionally meant a multi-stage pipeline with separate components for candidate generation and ranking at both the row and entity levels, where each choice affects the value of the others.
GenPage replaces that stack with a single generative model trained to answer one question: given everything known about the user and the request, what homepage should be generated to maximize user satisfaction? User history and request context become the prompt; the entire page is produced autoregressively as the response. Where generative recommenders such as TIGER, HSTU, and OneRec emit flat ranked lists, GenPage generates rows, entities, and layout together.
The stated motivations are end-to-end modeling (one transformer instead of a multi-stage stack, avoiding misaligned stage objectives and much feature engineering), whole-page optimization via reinforcement learning, cleaner scaling behavior with data, compute, and capacity, and extensibility to new content types, layouts, personalized UI components, and per-entity artwork. Production constraints — real-time serving latency, entity cold start, freshness, and strict business rules — shaped the techniques described below.
Representing the page as tokens
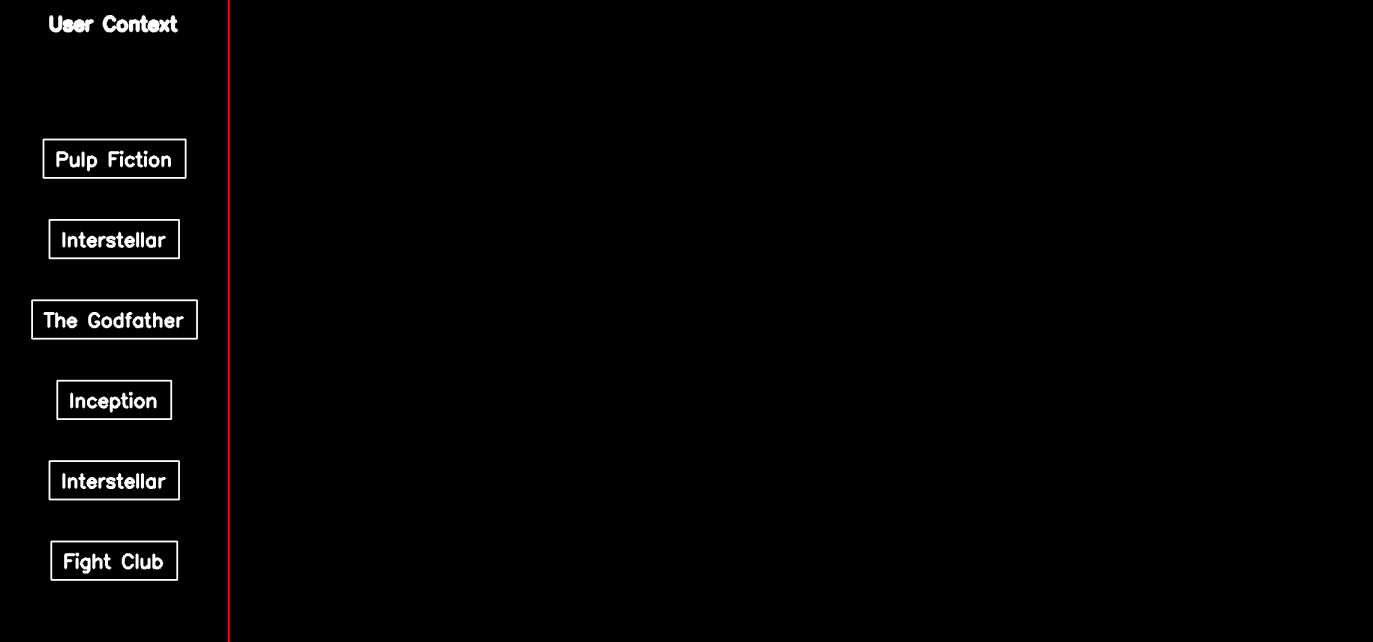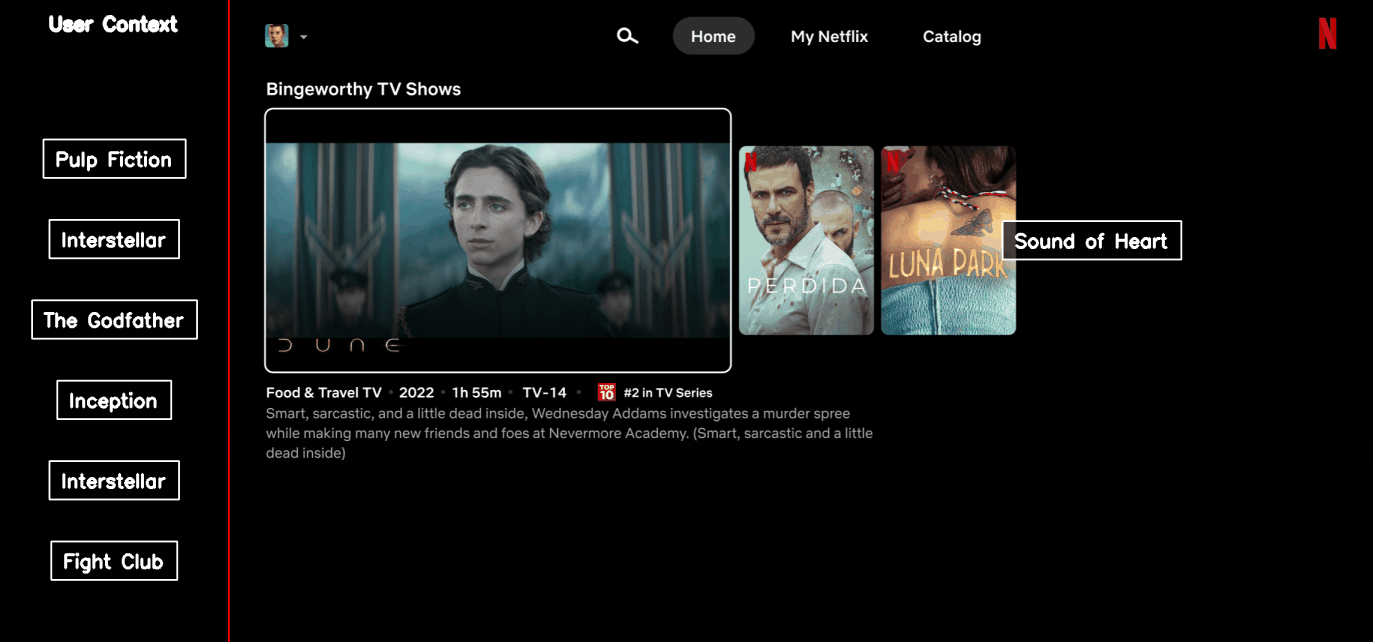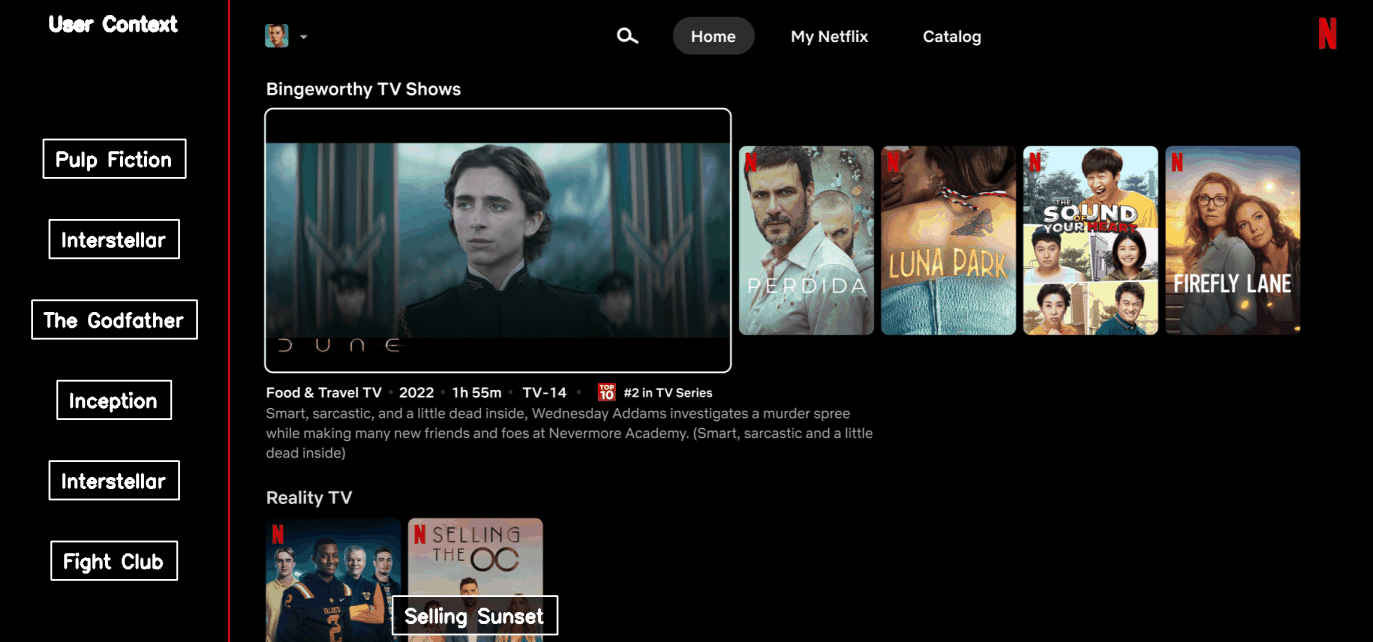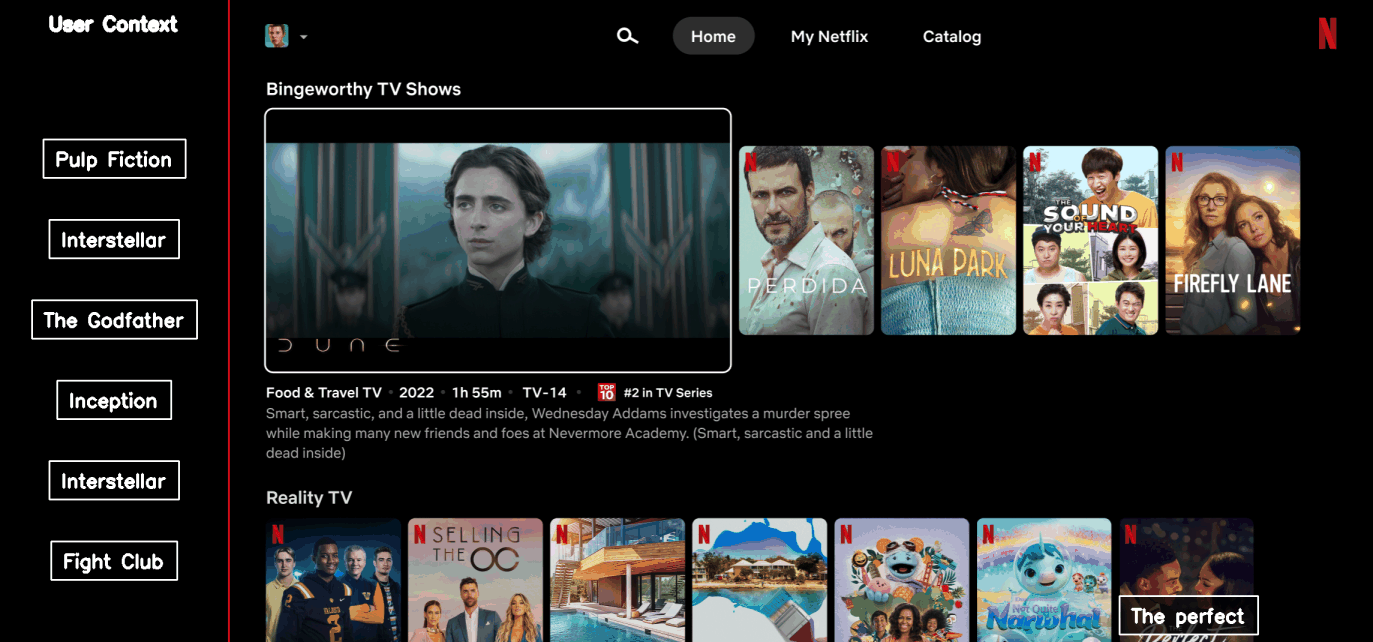
GenPage encodes both user context and the generated homepage as a single sequence of discrete tokens, covering the full structured layout so the page is generated holistically rather than scored row by row or entity by entity. Each training example is a homepage impression with three parts: context (engagement history, profile attributes, request context), page (rows and entities in layout order), and feedback (interactions such as play, thumbs-up, or abandonment). Only context and page are tokenized as inputs and outputs; feedback feeds the internal reward system.
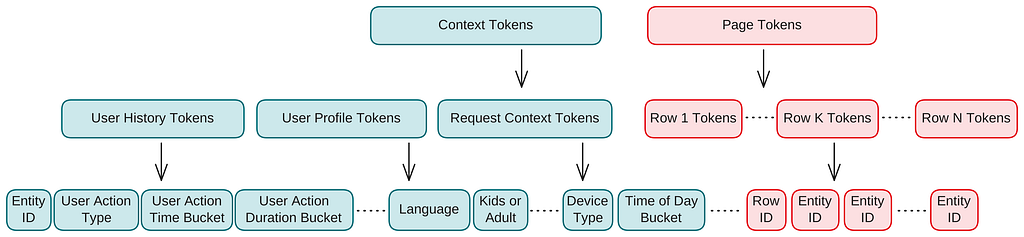
Rather than an off-the-shelf text tokenizer, the system uses a domain-specific one, an approach with precedent in recommender systems, computer vision, biology, and chemistry. It buys two things. First, efficiency: the event "User watched Orange Is the New Black for 50 minutes 30 days ago." costs 16 tokens under the GPT-5 tokenizer but compresses to 4 here — [Entity_ID], [Action_Type], [Action_Time_Bucket], [Action_Duration_Bucket] — cutting sequence length, inference cost, and latency. Second, product control: a direct mapping between tokens and product concepts makes it easier to constrain what the model can generate.
Token types
Context tokens cover user engagement history, profile, and request context. History is a sequence of actions, each carrying action type, entity ID, timestamp, and duration, and drawing on both explicit signals (play, add to My List, thumbs-up) and implicit ones (trailer views, details-page visits). Profile tokens capture attributes such as language and profile type; request context tokens encode time of day, day of week, and device. Special tokens mark segment boundaries, and continuous signals like timestamps and durations are bucketized into discrete ranges to keep the vocabulary finite. Sources too long to include raw — full impression history, for instance — are represented by summarized versions, an acknowledged form of handcrafted prompt engineering that end-to-end compression should eventually replace.
Page tokens are equally coarse: each entity and each row is a single token, serialized in layout order (left to right, then top to bottom). The entity and row vocabulary is refreshed daily. Entities still out of vocabulary at serving time fall back to semantic embedding fusion and fallback tokens.
The paradigm could extend to any output expressible as a linear token sequence — one-dimensional feeds or mixed layouts, customized row display sizes, personalized artwork — though these remain future work.
Paginated generation
The homepage is often generated incrementally, a few rows at a time, so recommendations can respond to in-session preferences. Before each pagination request, page tokens from previously generated rows are appended to the prompt along with the user's latest engagements on those rows, sourced from Netflix's real-time event-logging infrastructure.
Reward and model
Supervision comes from Netflix's internal reward system, tuned through online A/B testing to align with long-term satisfaction. It assigns a scalar reward to every impressed entity: a show binge-watched in one night scores higher than a movie watched for 10 minutes, and an abandoned impression scores negative. The page-level reward is the sum across all impressed entities on the page.
The model itself is a standard decoder-only transformer, chosen for simplicity and for the surrounding ecosystem of training and serving tooling. One detail matters: input embedding and output projection weights are untied, because pretraining optimizes a softmax over the vocabulary while weighted binary classification post-training optimizes per-token sigmoid scores.
Training
The recipe follows the LLM pattern — pretrain, then post-train — with two alternative post-training approaches. Weighted binary classification (WBC) is simpler to optimize and aligns with the entity-level objectives of existing production ranking models. RL is harder to evaluate and optimize but is the path to page-level optimization, plus test-time reasoning and multi-token entity representations.
Pretraining
Pretraining uses next-token prediction: given context tokens and a prefix of page tokens, predict the next page token, teaching the relationship between contexts and successful homepages. The examples resemble LLM supervised fine-tuning prompt-response pairs more than raw pretraining text; the stage is called pretraining because the model is trained from scratch rather than fine-tuned from a checkpoint. Recommenders have the opposite data problem from LLMs: instead of scarce labels, there is abundant feedback, so pretraining uses homepage impressions that received positive feedback in production, bootstrapping the model to imitate the existing system. That imitation is also the limitation — pretraining does not optimize reward magnitude, and repeatedly training on pages from earlier model versions risks model degeneration.
Post-training by WBC
WBC converts generation into token-level value prediction: the model estimates the value of each possible next row or entity token given the context and prefix generated so far. Because the homepage decomposes into per-token targets, credit assignment is built in, which makes the objective easier to optimize than page-level RL, and custom tokenization makes it practical — each token maps to one entity or row, so the reward system's scalar reward attaches directly. Row-level rewards are aggregated from their constituent entities. Each reward yields a binary label from its sign and a weight from its magnitude, optimized with a weighted binary cross-entropy loss on the corresponding logit, which can be read as a value estimate for generating that token at that position. Generation remains autoregressive: the model scores candidate tokens, takes the highest-value one, appends it, and repeats.
Post-training by RL
RL treats page generation as sequential decision-making and optimizes a page-level reward, capturing interactions across rows and entities such as diversity, stopping power, and page-level business constraints. It also opens the door to test-time reasoning — reasoning outputs functioning as a form of automated feature engineering — and to multi-token entities, where a show might need [Show_ID] plus [Episode_#], or a sequence of semantic ID tokens. In that setting WBC's per-token labeling becomes ambiguous, since one entity-level reward must be split across tokens, whereas RL optimizes sequence-level return.
Following the RLHF recipe, the team first trains a reward model that predicts the page-level reward for a generated page. This is distinct from the reward system: the system converts observed feedback for a page that was actually shown, while the reward model predicts the outcome for a candidate page without showing it, which is what allows optimization against arbitrary pages. Training against a reward model avoids the high variance of off-policy correction on logged or predicted propensities but risks reward hacking, so a KL penalty keeps the policy close to the pretrained checkpoint — itself trained to mimic the production policy — holding pages within the reward model's coverage.
The algorithm is Dr. GRPO, a variant of GRPO that mitigates biases in the training objective. Its components: prompts drawn from production user requests as context tokens; policy and reference models both initialized from the pretrained checkpoint, with the reference anchoring the KL penalty; and a dedicated transformer-based reward model, also initialized from the pretrained checkpoint, supervised by the sum of entity-level rewards from the internal reward system. Rule-based format rewards guide the policy further — the page should resemble a list of rows, and business-critical rows or entities should not appear too low on the page.
Production engineering
Cold start
New entities lack the interaction data needed for robust token embeddings, so GenPage uses two complementary strategies. Context injection puts metadata about new or time-sensitive entities, such as Live Now events, directly into the context tokens. Semantic embedding fusion represents each entity as a fusion of its learned ID embedding and a content-based embedding derived from synopses, cast, transcripts, genres, and video content; this fused vector is the transformer input for that token. During training, entity ID tokens are replaced with the generic fallback token at small probability so the model learns to recommend from content alone, giving a new entity a meaningful representation as soon as its metadata exists.
Multi-cadence incremental training
Retraining a large transformer daily from scratch is prohibitively expensive, but the model must track shifting trends and catalog additions. A cyclic schedule handles both: at a tunable cadence, a large-scale pretraining and post-training pass runs over a broad historical window; between passes, a daily incremental update continues post-training from the previous day's checkpoint on a mix of the latest data and a sampled subset of past data, which guards against overfitting and catastrophic forgetting.
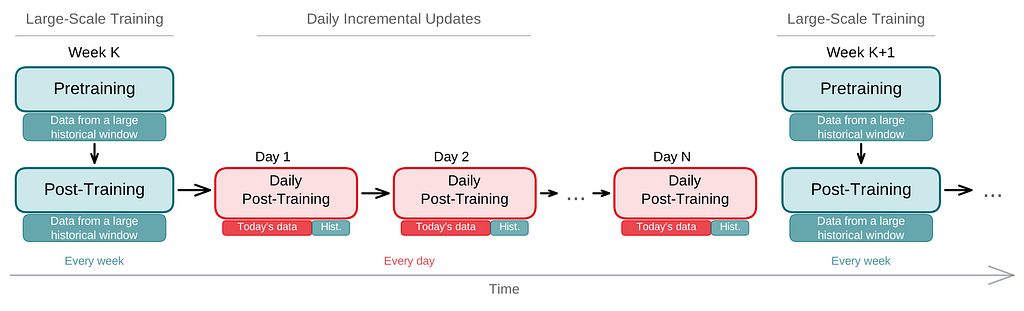
Fallback tokens absorb the daily influx of new tokens. New rows and entities initialize from [Row_Fallback_Token] or [Entity_Fallback_Token], and random replacement of a small percentage of known tokens with fallbacks during training teaches graceful handling of unknowns.
Constrained decoding for business rules
Structural constraints, deduplication, row pinning, and category consistency cannot be guaranteed by training signals alone, so they are enforced at inference through constrained decoding. At each autoregressive step, a mask of eligible tokens computed from the applicable rules is applied to the output logits, permitting only rule-compliant tokens. Custom tokenization makes this simple: with one token per entity and row, business rules map directly to token-level masks without the multi-token bookkeeping a text vocabulary would require. Pinning a row such as popular games at position 2 is a matter of masking all other tokens at that position.
Hybrid row decoding
Generating every entity token one at a time is expensive, and the first few entities in a row carry the most attention and shape the row's perceived theme. Hybrid row decoding therefore generates only the first few entities per row autoregressively, then, conditioned on that prefix, obtains logits for all eligible entities in a single forward pass and selects the top scorers subject to the same business-rule constraints. Autoregressive conditioning is preserved where it matters most, without the cost of decoding long rows token by token.
Offline findings
A series of ablations on internal data, run at roughly 200M parameters on held-out evaluation data unless noted, examined individual components. Because development was iterative, each study spans different configurations and data snapshots, so only relative comparisons within a study are meaningful.
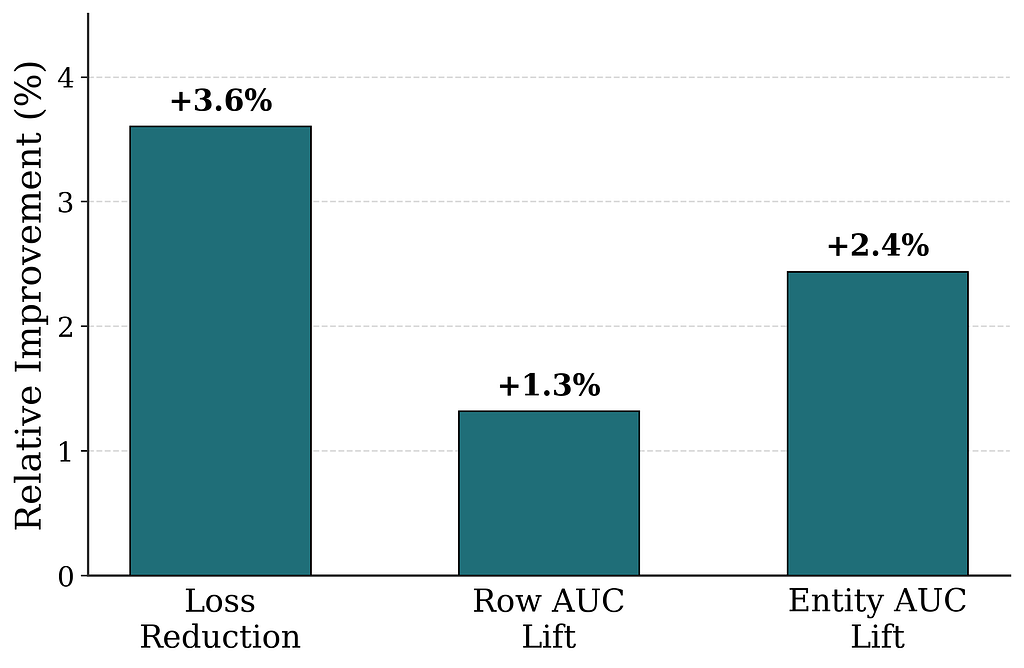
Pretraining helps. Comparing WBC post-training with and without a preceding next-token-prediction stage shows substantial improvement across all metrics (Figure 4). The absolute numbers look small but are large for a mature production system: an Entity AUC lift from 0.91 to 0.92, setting aside sample weighting, drops the misranking rate for a random positive-negative pair of impressed entities from 9% to 8% — rarely achieved by a single change in that regime.
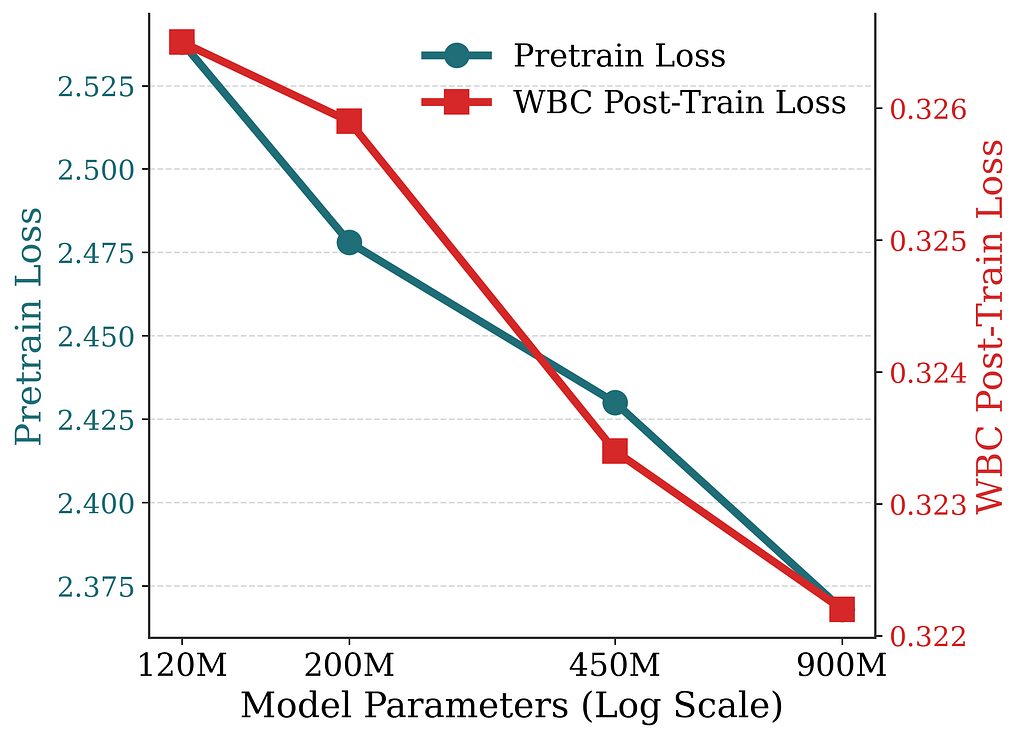
Scaling shows power-law-like behavior. Sweeping model size from ~120M to ~900M parameters (Figure 5), both the pretraining next-token-prediction loss and the WBC post-training loss fall in a power-law-like fashion.
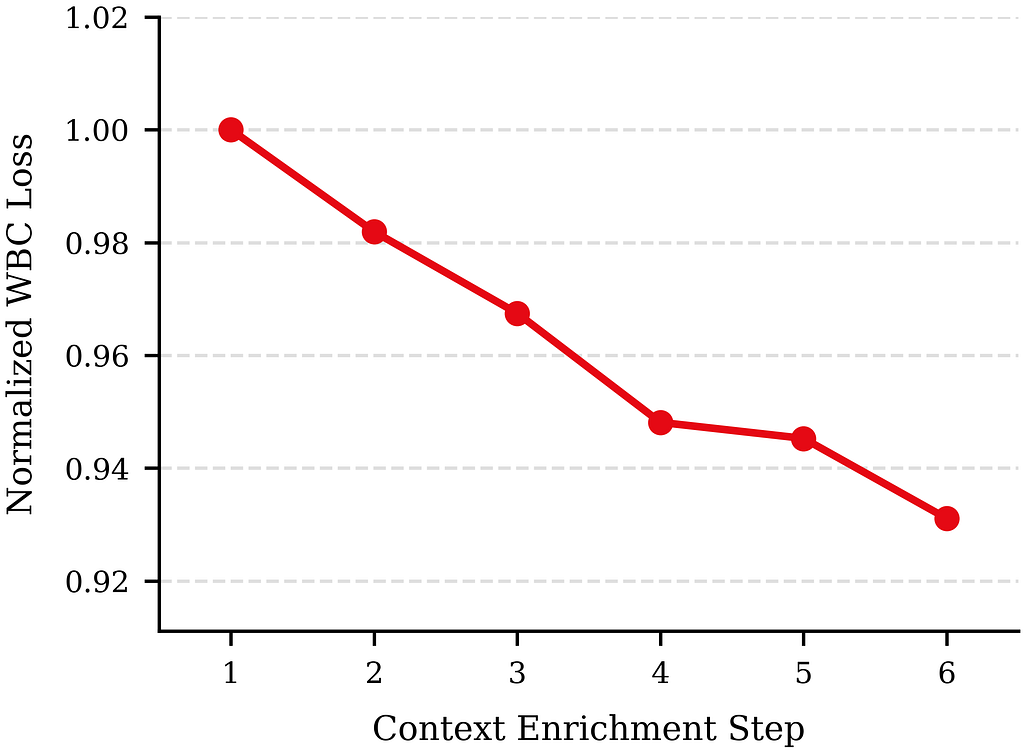
Context enrichment dominates capacity. Progressively adding data sources to the prompt and refining how each is tokenized reduces WBC loss substantially at fixed model size (Figure 6). The two sweeps span different axes and are not strictly comparable — roughly an order of magnitude in parameters versus the full trajectory of prompt design — but the gap is striking: scaling from 120M to 900M parameters cuts WBC loss by about 1.3%, while cumulative context enrichment yields around 6.9%. In several cases a single well-designed context addition beats the entire ~7.5× capacity scaling, suggesting personalization quality is bottlenecked first by the information and representation available and only then by capacity. Context enrichment should dominate until the context saturates.
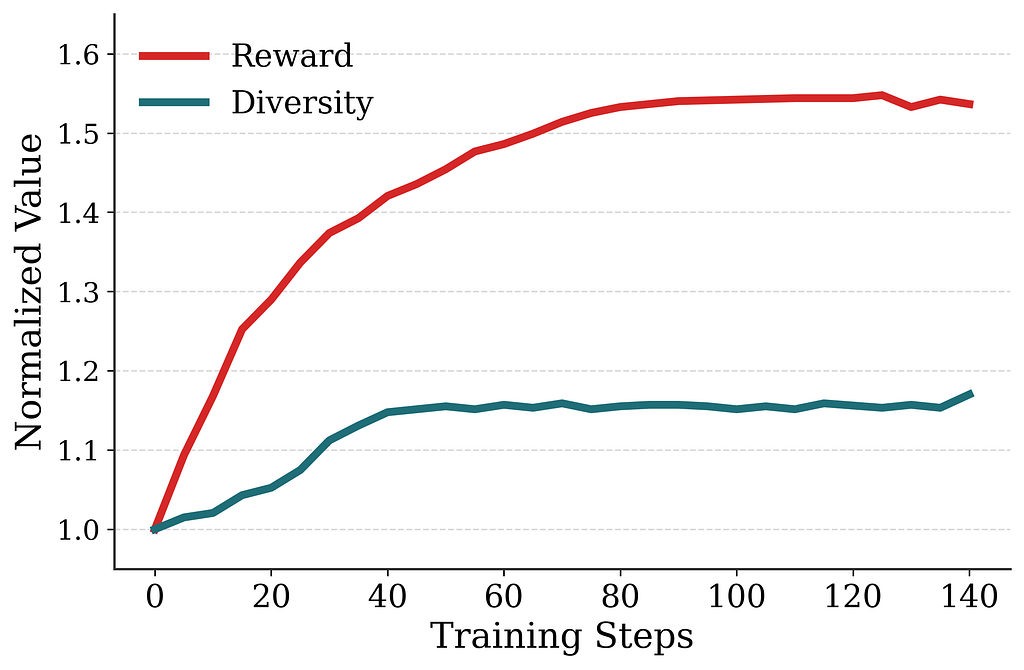
RL optimizes at the page level. Offline, RL post-training improves page-level reward over the pretrained checkpoint — largely confirmatory, since the reward is computed by the model the policy optimizes against — but homepage diversity, measured as pairwise embedding distance among entities on the page, also rises over training despite not being part of the objective (Figure 7). That indicates the policy is optimizing the page as a whole rather than each token in isolation.
Online results
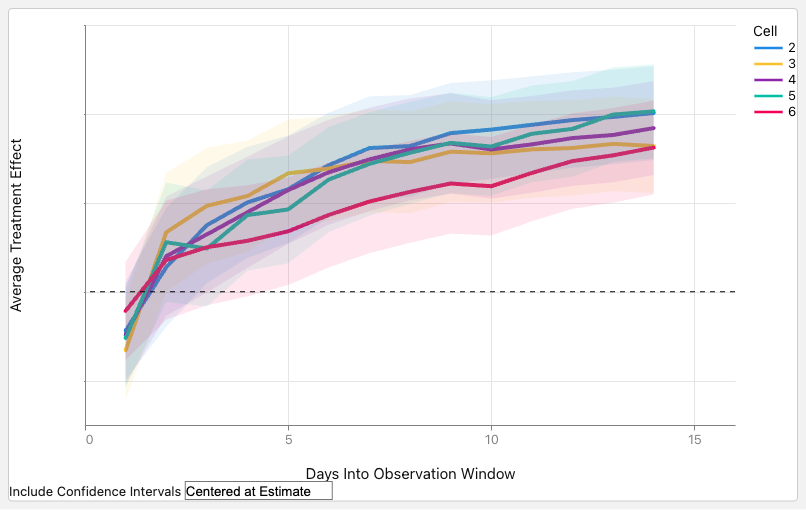
An online A/B test compared GenPage against the production homepage recommender, with GenPage decoding over the existing production row and entity candidate sets, which handle many business rules such as eligibility. All variants produced statistically significant improvements on the core user engagement metric used for launch decisions (p < 0.001) against the mature, highly optimized multi-stage baseline; the variants differed only in training-data configuration, and their comparable lifts suggest the gain is robust rather than configuration-specific.
Two side observations accompanied the win. The distribution of impressed entity categories shifted — new versus established titles, TV shows versus movies — in ways that were not explicitly optimized for and warrant further investigation. The team suspects the shifts reflect more precise personalization, consistent with higher impression efficiency, and that they surface production-inherited components such as the reward system that are not yet aligned with the generative paradigm. Separately, responsiveness to in-session signals was strong: recent actions quickly influenced subsequent recommendations and faded back to long-term preferences within a day or two, confirming effective attention to action timestamps and emerging without extensive manual feature engineering.
Latency also fell. Contrary to the assumption that generative models are slower, GenPage cut end-to-end serving latency by 20%, replacing multiple ranking stages and heavy feature computation with one transformer over raw tokenized inputs; custom tokenization and hybrid row decoding further reduced decoding steps. The reduction did not exhaust the available optimizations, and the headroom can be reinvested in capacity or richer prompts.
Open directions
Long context still relies on handcrafted summarization, and LLM-style capabilities — language, multimodality, reasoning — have not yet been incorporated. One promising direction is a hybrid tokenization combining domain-specific tokens with generic text tokens, retaining structured control while inheriting general-purpose LLM strengths; conceptually, this introduces an additional recommendation modality into an LLM. More broadly, the team expects LLM advances to transfer naturally to this setting, and the boundary between LLMs and recommender systems to blur.