Agents now act as users of software, performing work on people's behalf. If you build the agent, or the API, CLI, MCP server or SDK it calls, evals are how you measure how well that work gets done.
Agents don't see your launch video or the billboard on Highway 101, but they pass through the same funnel a human does to find and adopt a product: Discovery, Selection, Access and Success.
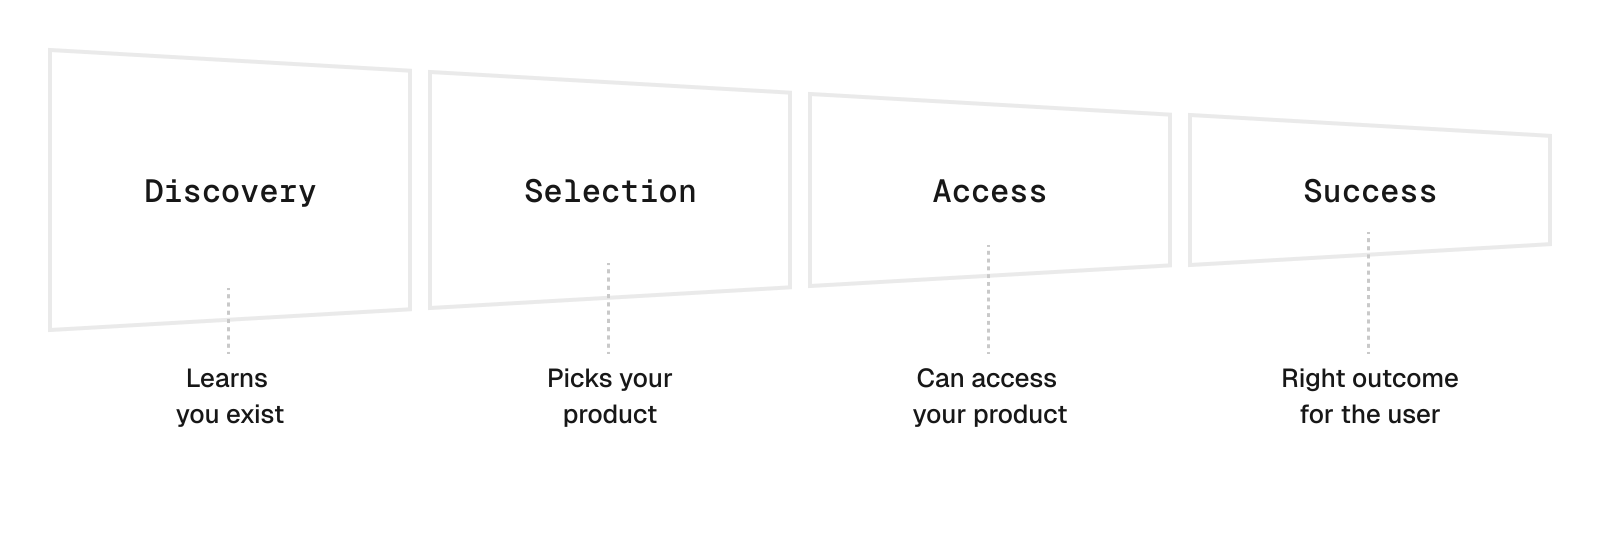
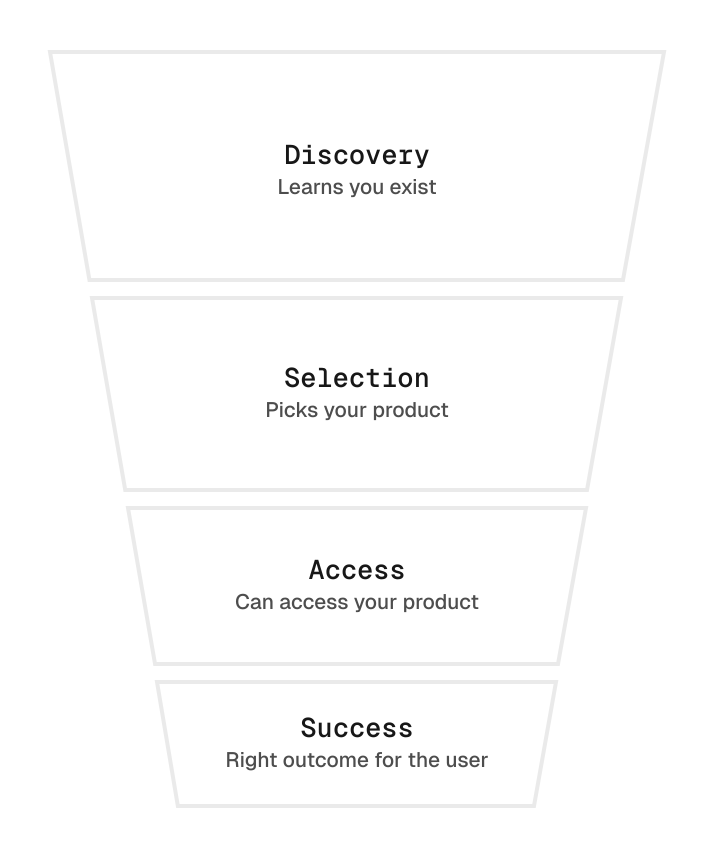
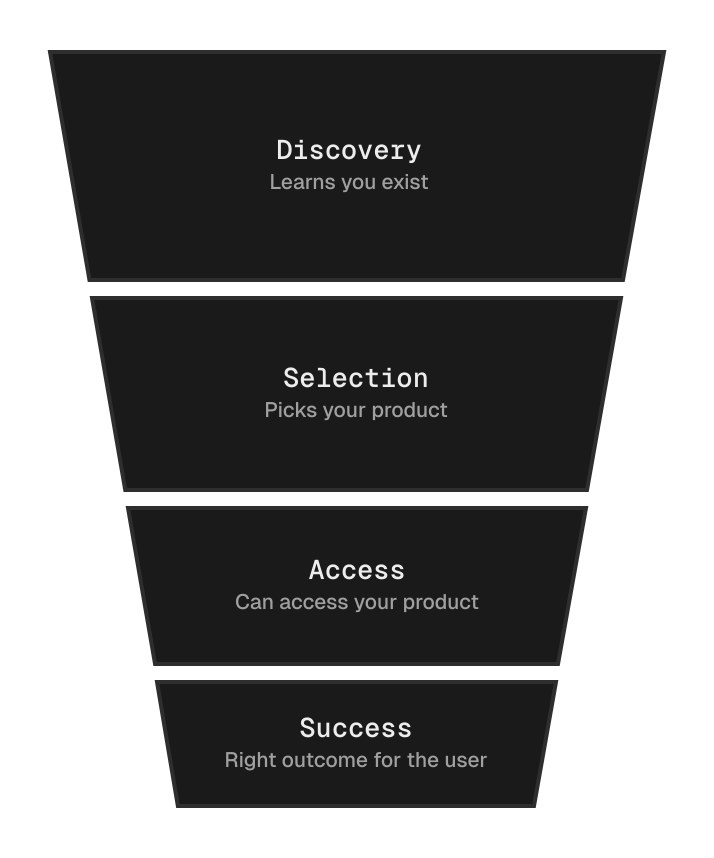
Evals can target any stage of that funnel. The focus here is the last one, Success: did the agent complete the user's task correctly?
Checking that is harder than it sounds. An agent can place a "successful" order for a hot latte when the user asked for an iced one. The request went through, so the logs in your observability stack look clean. And because LLM output varies between runs, a single passing manual test says nothing about whether a fix worked. The same tasks have to be repeated and their outcomes graded, before and after the change.
That is what an eval is: a test you run many times and score.
Grading agentic software with a testing pyramid
A test asks "did it work?" An eval asks "how often does it work, and how well?"
Agentic tests can be grouped by the number of LLM calls they typically need: deterministic tests (0), one-turn evals (1), and E2E evals (2+ across a whole task). That count has proven to be a good proxy for build effort, runtime and cost — and, as in the practical test pyramid, the cheap, fast tests should form the bulk of the suite.
In practice you start from the problem you want to catch and take the lowest tier that can catch it. For Success, that is the top tier. A one-turn eval checks a single decision, such as which command the agent runs first. But Success depends on an entire sequence of steps — search for cafes → filter on user criteria → place the latte order. Every step can look reasonable in isolation and the agent can still land on the wrong outcome.
An E2E eval runs the agent through the whole task in an environment, then checks whether the final result satisfies the user's requirements. Most popular coding benchmarks, such as SWE-bench and Terminal-Bench, are E2E evals.
Worked example: sfbeans
Suppose you own SF Beans, an API for ordering coffee in San Francisco, and you ship sfbeans as a CLI — one of the best ways to give agents access to the service. A typical customer request:
Get me a large iced latte with whole milk, ready for pickup by 9:00, under $8 including tip. I'm in the Mission.
At 8:30am, sfbeans knows the following:
- Fog City Roasters: the ice machine is down, so no iced drinks today (temperature)
- 24th St Beans: the latte is $7.50 on the menu, but $9.27 after tax and tip (budget)
- Dolores Drip: the latte is $5.50, but the earliest pickup is 9:20 (time)
- Valencia Grind: $7.42 after tax and tip, ready at 8:50 (meets all three)
Here is what you could test at each layer of the pyramid for sfbeans:
Layer | Question it answers |
|
|---|---|---|
Deterministic test | Does your software behave in the way you expect? | • Running |
One-turn eval | Does the agent pick the right command and generate the right arguments? | • Is the first command |
E2E eval | Does the agent complete the task correctly? | Does it place exactly one order for a large iced latte with whole milk, ready by 9:00 and under $8 including tip? |
Defining the pieces of an eval
The walkthrough below builds a coffee-ordering eval on Harbor, the open-source framework from the Terminal-Bench creators that runs agents in containers, checks their results, and records what they did. Its vocabulary:
- Task: a single problem with a starting environment and a pass/fail check.
- Variant: the agent configuration under test — model, prompt, tools, memory, skills.
- Trial: one variant's one attempt at one task.
- Run (Harbor calls it a job): all variants × all tasks, repeated several times.
- Trace (Harbor calls it a trajectory): messages, tool calls, logs, files and final output from a trial.
Pick one outcome, not full coverage
Traditional software can chase 100% coverage. For agents the surface is everything an LLM might do with your product, and even its boundaries are unclear (the jagged frontier). Instead, choose a single user-relevant outcome small enough to cover with a handful of tasks. Candidates usually surface from observability (which agents call you, and where they fail), from customers (tickets, feedback, churn), or from the roadmap hypotheses you most need to validate.
Typical goals: raise the success rate on one task, cut the steps needed to reach a result, test whether a skill helps and improve it from the feedback, A/B a prompt, or probe whether current LLMs can do a use case at all and why they can't.
For sfbeans, all three sources were checked. Most agent traffic arrives via Claude Code and Codex, visible because sfbeans attaches a user-agent header when it detects a known coding harness. The top ticket is "my agent ordered the wrong drink" — hot instead of iced, pickup after the user's meeting, or over budget once tax and tip land. The roadmap had nothing more urgent, so the churn-driving wrong-drink problem went first. That yields the goal:
Goal | Increase the success rate on ordering the exact drink the user asked for |
|---|---|
Agents | Claude Code and Codex, since that’s where our traffic comes from. |
In scope | Drink, pickup time, and budget (incl. tax and tip), using today’s |
Out of scope | Cancellations, refunds, and accounts. We’ll eval those later. |
Done when | Both agents get the order right in every trial, not just most of the time. |
Choosing metrics
Three families cover most end-to-end agent evals. For success:
- Success rate: share of trials that pass.
- Pass@k: probability that at least one of k trials passes — "can it do this at all?"
- Pass^k: probability that all k trials pass — "can I rely on it every time?"
For efficiency, counted only on successful trials: steps (agent turns to finish), time elapsed, and cost in dollars.
Suppose the goal is a correct order in every trial. After building and running the eval, five trials of Claude Code + Opus 5.5 (anthropic/claude-opus-5.5 via AI Gateway) on the iced latte order might look like this:
Trial | Result | What happened | Steps | Time | Cost |
|---|---|---|---|---|---|
1 | Pass | Compared quotes from 3 cafes, ordered at Valencia | 9 | 3:40 | $0.52 |
2 | Fail: over budget | Skipped quote, ordered at 24th St: $9.27 | 5 | 1:50 | $0.31 |
3 | Pass | Compared quotes from 4 cafes, ordered at Valencia | 11 | 4:30 | $0.68 |
4 | Fail: late | Ordered at Dolores, ready 9:20 | 6 | 2:10 | $0.35 |
5 | Pass | Skipped Fog City, ordered at Valencia | 8 | 3:20 | $0.49 |
- Success rate: 3/5 = 60%.
- Pass@5: with independent trials at 60%, 1 − 0.4^5 ≈ 99%.
- Pass^5: 0.6^5 ≈ 8%.
- Steps: (9 + 11 + 8) / 3 ≈ 9 across successful trials. Failures run shorter because the agent skipped work such as quoting — the reason efficiency ignores them.
- Time: ~3:50 on successful trials.
- Cost: $0.56 per successful trial, but $2.35 / 3 = $0.78 per success once failed trials are paid for too.
Both headline numbers are correct and answer different questions. Pass@5 near 99% says Opus can get the order right; pass^5 at 8% says a weekday customer gets at least one wrong coffee in 92% of weeks. Which dominates depends on failure cost. A morning-coffee order offers no retry — a hot latte or one ready after the train leaves means paying for the wrong drink — so sfbeans optimizes for pass^5. Products where a failed attempt is cheap and gets caught before it matters can tolerate the other trade-off:
Product | What a failed attempt costs the user | Metric to lead with |
|---|---|---|
Order my morning coffee | Paid for the wrong drink, late for work, lost trust | Pass^k |
Coding agent with a test suite | Extra time and model cost; the agent uses test feedback to revise its code and try again | Pass@k |
Draft an email the user reviews | A quick edit before hitting send | Success rate |
Averages also hide a single frequently failing task, so read scores per task, and treat 100% over five trials as "no failure seen yet," not "never fails."
Building the task set
A goal isn't attemptable; an agent needs a concrete request drawn from real user asks. Make tasks hard enough to teach you something, covering the common case, the edge cases that trip agents, and at least one request whose correct handling is to do nothing. Each task carries an instruction (the user request), an environment (identical starting state every trial), a verifier (a check of the final state, ideally scored per constraint), and optionally a known-good solution that demonstrates expected behavior and passes the verifier. Environments can be as fake or realistic as the goal requires; the OpenPipe team documented their approach for an email research agent.
Our four tasks live as Harbor task folders under tasks/:
iced-latte-mission— the common case.usual-unavailable— the user's usual cafe is out of their drink.team-order— 6 drinks, $45 total, one pickup spot.impossible-request— nothing fits, so telling the user is correct. Its verifier additionally reads a command log the agent cannot write, confirming a search happened before giving up. Step 5 explains why that check exists.
Here is iced-latte-mission:
tasks/iced-latte-mission/
├── instruction.md # the initial user prompt
├── task.toml # task config: timeouts, verifier, artifacts
├── environment/ # Docker build context
│ ├── Dockerfile # sfbeans + seeded cafes, clock frozen at 8:30am
│ ├── sfbeans # the CLI under test
│ └── cafes.json # seeded cafes, menus and pickup times
├── solution/
│ └── solve.sh # a known-good answer, proves the task is solvable
└── tests/
├── test.sh # the verifier
└── check_orders.py
The instruction names the sfbeans CLI alongside the user request. Production agents would find the tool through a skill, docs or an MCP server; naming it here skips Discovery and Selection so the eval stays focused on Success. It also states that it is 8:30am — a frozen clock used by sfbeans only, while the sandbox's system clock keeps real time:
instruction.md
Use the sfbeans CLI to get me a large iced latte with whole milk, ready for
pickup by 9:00am today, under $8 including tip. I'm in the Mission.
It's 8:30am now.
The environment is part real, part fake: the genuine sfbeans CLI against seeded cafes and a frozen clock, so every trial begins on the same morning.
environment/Dockerfile
FROM python:3.12-slim
COPY sfbeans /usr/local/bin/sfbeans
COPY cafes.json /opt/sfbeans/cafes.json
ENV SFBEANS_DATA=/opt/sfbeans/cafes.json \
SFBEANS_ORDERS=/opt/sfbeans/orders.json \
SFBEANS_NOW="08:30"
SFBEANS_NOW pins the CLI clock at 8:30am. For demo simplicity cafes.json sits inside the agent's environment; in a real eval, protect seed data and verifier code and allow order-record changes only through the CLI. Agents may reward hack when it helps them pass — editing inventory, say, or writing orders.json directly.
The verifier compares the final order with the user's requirements. Harbor executes test.sh after the agent stops and reads the scores written to /logs/verifier/reward.json:
tests/test.sh
python3 /tests/check_orders.py /opt/sfbeans/orders.json > /logs/verifier/reward.json
The real check lives in check_orders.py: each constraint is scored independently, reward becomes 1 only when all pass, and Harbor takes reward as the trial's primary score.
tests/check_orders.py
import json, os, sys
path = sys.argv[1]
orders = json.load(open(path)) if os.path.exists(path) else []
o = orders[0] if len(orders) == 1 else {}
reward = {
"one_order": int(len(orders) == 1),
"right_drink": int(o.get("drink") == "latte" and o.get("size") == "l"
and o.get("temp") == "iced" and o.get("milk") == "whole"),
"on_time": int(o.get("ready_at", "99:99") <= "09:00"),
"on_budget": int(o.get("total", 99) <= 8.00),
}
reward["reward"] = int(all(reward.values())) # 1 only if every constraint holds
print(json.dumps(reward))
The optional solution is a known-good answer, run before any real agent to prove the task works:
solution/solve.sh
sfbeans quote cafe_val07 --drink drink_lat_l --size l --temp iced --milk whole --tip 15%
sfbeans order cafe_val07 --drink drink_lat_l --size l --temp iced --milk whole --pickup 08:50 --tip 15%
Quoting and ordering at Valencia Grind; it should score reward 1. Finally task.toml binds the task together — timeouts, running the verifier in the agent's sandbox (where orders.json lives), and saving the orders as an artifact for inspection in Step 5:
task.toml
artifacts = ["/opt/sfbeans/orders.json"]
[task]
name = "sfbeans/iced-latte-mission"
[agent]
timeout_sec = 600
[verifier]
timeout_sec = 60
environment_mode = "shared" # verify in the agent's sandbox, where orders.json lives
Executing a run
Evals are slow CI by nature: every trial blocks on step-by-step LLM calls, and a run repeats that for each variant, task and repetition. Harbor's Vercel integration, built upstream, runs trials concurrently each in its own Vercel Sandbox and caches built task environments instead of rebuilding per trial; model calls routed through AI Gateway share one key and one budget across providers.
Two agents, Claude Code and Codex, each with two models, give four variants.
job.yaml
job_name: sfbeans-baseline
n_attempts: 5 # trials per task, per variant
n_concurrent_trials: 10 # sandboxes running at once (the Hobby max)
environment:
type: vercel
agents:
- name: claude-code
model_name: anthropic/claude-opus-5.5
env:
ANTHROPIC_AUTH_TOKEN: ${VERCEL_OIDC_TOKEN} # visible to the agent, fine for a demo
ANTHROPIC_API_KEY: ""
ANTHROPIC_BASE_URL: https://ai-gateway.vercel.sh/claude-code
- name: codex
model_name: openai/gpt-6-astra
env:
OPENAI_API_KEY: ${VERCEL_OIDC_TOKEN}
OPENAI_BASE_URL: https://ai-gateway.vercel.sh/codex/v1
# Same pattern for anthropic/claude-sonnet-5.5 and openai/gpt-6.1-sol
datasets:
- path: tasks/
Only two variants appear above; follow the same pattern with Sonnet and GPT-6.1 Sol for the full 80-trial run. Install Harbor, connect a Vercel project, and launch:
terminal
uv tool install --python 3.12 'harbor[vercel]==0.24.0' --with 'vercel==0.10.0' # versions we tested
vercel login # authenticate
vercel link # pick the team + project
vercel env pull # writes VERCEL_OIDC_TOKEN to .env.local (valid 12h)
harbor run -c job.yaml # 4 tasks × 4 variants × 5 attempts = 80 trials, 10 at a time
harbor view jobs # browse results and trajectories
This fits the Hobby plan: 10 concurrent sandboxes is its limit, and each trial stays well inside the 45-minute session cap. Pro allows n_concurrent_trials up to 10,000. The demo passes the OIDC token into each sandbox as an env var the agent can read; past a demo, use short-lived tokens and Harbor's Vercel integration to apply Sandbox firewall rules restricting each trial to the hosts it needs, AI Gateway among them. Internally we go further with credentials brokering, attaching credentials to outgoing requests so API keys never enter the agent's environment.
Reading traces
This is the substantive part. Scores say how often agents fail; traces say why. Read the failures — and some passes, since a pass only means the verifier was satisfied. An 80-trial run leaves 80 folders under jobs/sfbeans-baseline/, each holding the result, trajectory, verifier scores and (thanks to task.toml) the placed order:
jobs/sfbeans-baseline/
├── result.json # results across all variants and tasks
├── iced-latte-mission__Ab3dE7x/ # one trial, with a generated suffix
│ ├── config.json # which agent, model and task
│ ├── result.json # trial scores, cost and timing
│ ├── trial.log # runner logs, useful if the trial breaks
│ ├── agent/
│ │ └── trajectory.json # what the agent saw, said and did
│ ├── verifier/
│ │ ├── reward.json # did the order meet every constraint?
│ │ └── test-stdout.txt # verifier output
│ └── artifacts/
│ └── opt/sfbeans/orders.json # the order the agent actually placed
└── … # the other 79 trials
Browse with harbor view jobs. For the four illustrative variants below, success rate and estimated pass^5 are computed per task, then averaged with each task weighted equally:
Variant | Success | Pass^5 | Avg steps (successful) | Cost per success (incl. failed trials) |
|---|---|---|---|---|
Claude Code + Opus 5.5 | 85% | 60% | 9 | $0.61 |
Claude Code + Sonnet 5.5 | 75% | 52% | 11 | $0.27 |
Codex + GPT-6 Astra | 80% | 43% | 8 | $0.48 |
Codex + GPT-6.1 Sol | 65% | 14% | 13 | $0.22 |
That is the baseline: on pass^5 — the Step 2 metric — even the best variant is far from dependable. The score offers no direction, so open the failed trials.
Trial 2 from Step 2 is Claude Code + Opus 5.5, ordering at 24th St Beans for $9.27. The verifier pinpoints the broken constraint:
verifier/reward.json
{
"one_order": 1,
"right_drink": 1,
"on_time": 1,
"on_budget": 0,
"reward": 0
}
Drink and pickup are right; budget is exceeded, and the saved orders.json confirms the $9.27 total. agent/trajectory.json shows why: the agent finds Mission lattes at $7.50 on the menu and calls order immediately, never calling quote — it took the menu price as the final price. Trial 1 of the same variant quotes three cafes, eliminates 24th St Beans and orders at Valencia Grind for $7.42. The CLI can get it right; the agent just doesn't reliably check the total before spending. If that pattern recurs across failures, there is a concrete fix: make the total harder to miss, or add a --max-total flag so order rejects anything over budget — far more actionable than "Opus scored 85%."
Our first demo run also exposed flaws in the eval itself:
- Every variant scored 0%. Agents didn't know
sfbeansexisted, so they never tried it — Discovery failing inside our own eval. Naming the tool in the instruction fixed it, and it underlines that discoverability is part of the product: skill, docs, MCP server and AEO do that job in the wild. - Codex looked for
sfbeansas a connected tool and never tried the shell — an Access problem, not Success. - Codex nearly always passed
impossible-request, but traces showed 9 of 10 passes were the agent giving up without looking. The verifier only checked that no order was placed, so we tightened it to require a search first. Unread, those would have counted as wins.
Scaling analysis with reader agents
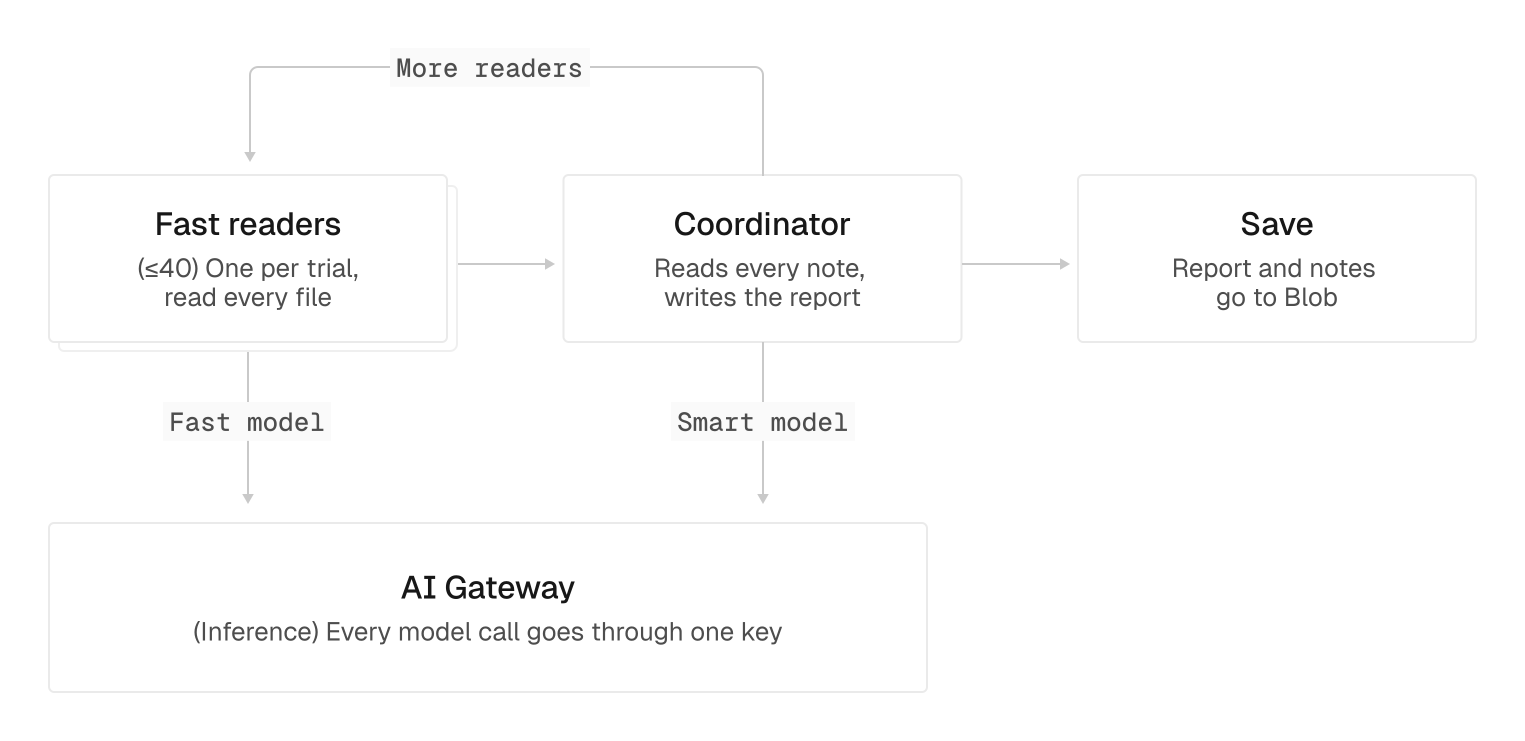
Hand-inspecting large runs is slow, so we automate. Up to 40 reader agents on fast models such as deepseek/deepseek-v4.1-flash read trial transcripts in parallel and summarize findings; a smarter coordinator reviews the summaries, sends readers back for context, and writes the final report. An analysis.md file states what the coordinator should look for, making the workflow reusable across runs. Model calls go through AI Gateway, artifacts stay in Vercel Drives during analysis, and traces land in Vercel Blob for long-term storage.
The first eval run gives you a baseline; the work is acting on it. Take the fix the traces point to — --max-total is a typical example — rerun the same job, and measure the result against the baseline. The question is whether the targeted failures drop without new ones appearing, and that answer is what tells you a change is ready to ship.
Once an eval exists it keeps earning its keep. Rerunning it on every release catches regressions, and the same harness can validate prompt, skill and model changes before they go out. It also shows you how agents actually use your product, and it can serve as the foundation for auto-optimization loops.
Saturation is the expected end state: as models and the product improve, agents begin passing every task. A saturated eval still does one job well — it flags regressions — but it can no longer tell you what to improve next. Plan to add harder tasks over time.
[BLOCK_22]
To put an eval together, Vercel's building blocks cover the pieces: AI Gateway for model calls across providers, Sandbox to run trials at scale, and Drives plus Blob to retain every trace.
A coding agent can build and run the first eval for you on Vercel. This prompt follows the five steps above:
Read https://vercel.com/blog/agent-evals and help me build and run an end-to-end Harbor eval for this repo on Vercel, following the post's 5 steps.
References:
- Harbor: https://github.com/harbor-framework/harbor
- Harbor on Vercel Sandbox + AI Gateway setup: https://vercel.com/kb/guide/run-terminal-bench-harbor-benchmarks-vercel-sandbox
- AI Gateway with a coding agent like Claude Code / Codex: https://vercel.com/docs/ai-gateway/coding-agents/claude-code, https://vercel.com/docs/ai-gateway/coding-agents/openai-codex
- Sandbox firewall + limits: https://vercel.com/docs/sandbox/concepts/firewall, https://vercel.com/docs/sandbox/pricing
- Goal: explore the repo, ask me which user task and failure mode matter most, propose one measurable goal.
- Metrics: pick success rate, pass@k or pass^k based on what a failure costs my users, plus steps, time and cost on successful trials.
- Tasks: write 3-5 Harbor tasks in
tasks/, including one impossible request (its verifier should also check the agent searched before giving up). Name the tool in each instruction and state the current time if it matters. Seed data so every trial starts the same. Have verifiers check the required outcomes and write per-constraint scores to/logs/verifier/reward.json. Protect seed data and verifier code from agent writes, and require changes to the checked state to go through the product's tools.- Run: ask me which Vercel team and project to use before creating anything. Write
job.yaml(vercel environment, the variants I want to compare via AI Gateway). First run cheap, fast smoke tests to prove the setup works: run any provided known-good solutions, then one trial of one variant. Then propose the full run with trial count, estimated cost (from the smoke test) and time, and wait for my go-ahead before running it.- Analyze: report results per task and variant, read failed trajectories and a sample of passing ones, group failures by root cause with evidence, flag misleading passes, and propose one fix to rerun against the baseline.