Shipping AI: What Actually Moves the Needle
“How do you build AI features people want and trust?” That question guided a panel of product managers from Figma, Duolingo, Asana, and LinkedIn as they discussed the realities of bringing AI-powered products to market. Their answers suggest that success hinges less on the sophistication of the underlying model and more on discipline around user research, experimentation, and honest communication about what AI can—and cannot—do.
Start With Real Friction, Not Model Capability
A recurring theme: don't begin with the technology. The PMs emphasized identifying a specific, painful user problem first, then determining whether AI is even the right tool to solve it. This often means resisting the temptation to bolt AI onto a feature simply because it's technically possible. The panel stressed that user research is non-negotiable; talking to actual users early helps distinguish genuinely useful applications from novelty. Instead of building for the “wow” factor, aim for seamless integration—AI should reduce friction invisibly, not add another layer of complexity for the user to manage.
Set the Right Bar for Quality
A critical operational hurdle is calibrating expectations for model performance. In traditional software, a bug is binary: it works or it doesn't. With AI, outputs are probabilistic, meaning perfection is an unrealistic target. PMs reported spending significant time defining their “quality bar” for minimum viable accuracy, often choosing to constrain the scope of a feature to ensure reliability. Shipping a narrow but dependable AI capability beats shipping a broad, erratic one. The discussion also stressed explaining limitations transparently in the UI—users are more likely to trust an AI that openly signals uncertainty than one that presents every answer with false confidence.
Measure Success Beyond Accuracy
Offline accuracy metrics matter, but they must be paired with tracking real-world impact. When it comes to rolling out AI features, teams need to measure not only direct engagement with prompts but the ripple effect on long-term user retention and core workflow efficiency. For an AI feature to be truly valuable, it must justify its existence through observable behavior changes farther down the funnel.
Given the unpredictable nature of generative AI, rigorous experimentation—A/B testing against control groups where possible—becomes even more crucial than for standard feature launches. Since each user interaction with an LLM is unique, combining controlled comparisons with qualitative feedback is crucial for detecting subtle flaws that quantitative metrics may miss. The PMs advised a tight loop: ship small, observe real usage patterns, and iterate daily.
Cross-Functional Partnership is Not Optional
Shipping AI shifts the burden on team structure. The rate of iteration demanded by large language models requires engineers, designers, and PMs to work almost as one unit. Designers cannot simply hand off high-fidelity mockups. Instead, they must prototype with live models to understand the variability of output, ensuring the interface accommodates imperfect or unexpected responses. PMs serve as the ethical guardrails, keeping the team focused on the human impact of the system.
A touch of skepticism about marketing hype is essential at every step. The role of a PM, one panelist suggested, is to sift through vendor promises and apply critical thinking about where AI genuinely creates value without compromising data privacy or creating unintended consequences. The discussion left a clear impression: the core constraints of product management—empathy, iteration, and delivery—are non-negotiable pillars, even when the technology feels brand new.
Shipping AI: Product leaders on building features that survive the hype cycle
A little over a year after ChatGPT's launch — and its explosive growth to over 100 million active users in two months — the AI arms race shows no signs of slowing. The pressure to ship AI-powered features is intense, but separating substance from spectacle requires discipline. Product leaders at Figma, Duolingo, Asana, and LinkedIn shared how they navigate the gap between hype and genuinely useful products.
Start with the problem, not the technology
“AI is a hammer and everybody is looking for nails,” says Conor Woods, Product Manager at Figma. Teams should begin with real user pain points and only then consider whether AI genuinely helps. Woods applies three tests:
- Is there an existing large data set? LLMs like OpenAI’s GPT-4 excel at organizing information that already exists—summaries, for instance—but struggle to invent entirely new experiences without significant prompt engineering.
- Can you tolerate imperfection? LLMs produce hallucinations and outright falsehoods. Problems demanding 100% accuracy aren't suitable candidates.
- Is AI masking bad UX? AI can't fix a fundamentally broken ecosystem — it only adds complexity, like a smart assistant searching across a cluttered phone.
Asana has an even simpler filter: does it save users time? Its Smart Status feature drafts status updates in seconds. “They can right away go from, ‘I spend 20 minutes a week doing this’ to ‘now I’m going to spend two minutes per week.’ The ROI is super clear to them,” says Rodrigo Davies, Product Lead for AI at Asana.
AI is a hammer and everybody is looking for nails.“AI is a hammer and everybody is looking for nails.”
Be aggressively specific about outcomes
Generative AI's versatility creates ambiguity during product definition. “When you describe an AI feature with words (‘we’ll summarize text’), everyone ends up with a slightly different interpretation in their head,” says Cemre Güngör, PM Manager at Figma. A summary could mean grasping the gist, extracting action items, or surfacing notable quotes.
Güngör recommends writing concrete prompt and output examples from the outset. This aligns cross-functional teams on exact expectations and, during implementation, serves as a benchmark for whether the feature is tracking toward its goal. Without that specificity, the project risks careening off in unintended directions.
Chat interfaces are a starting point, not the destination
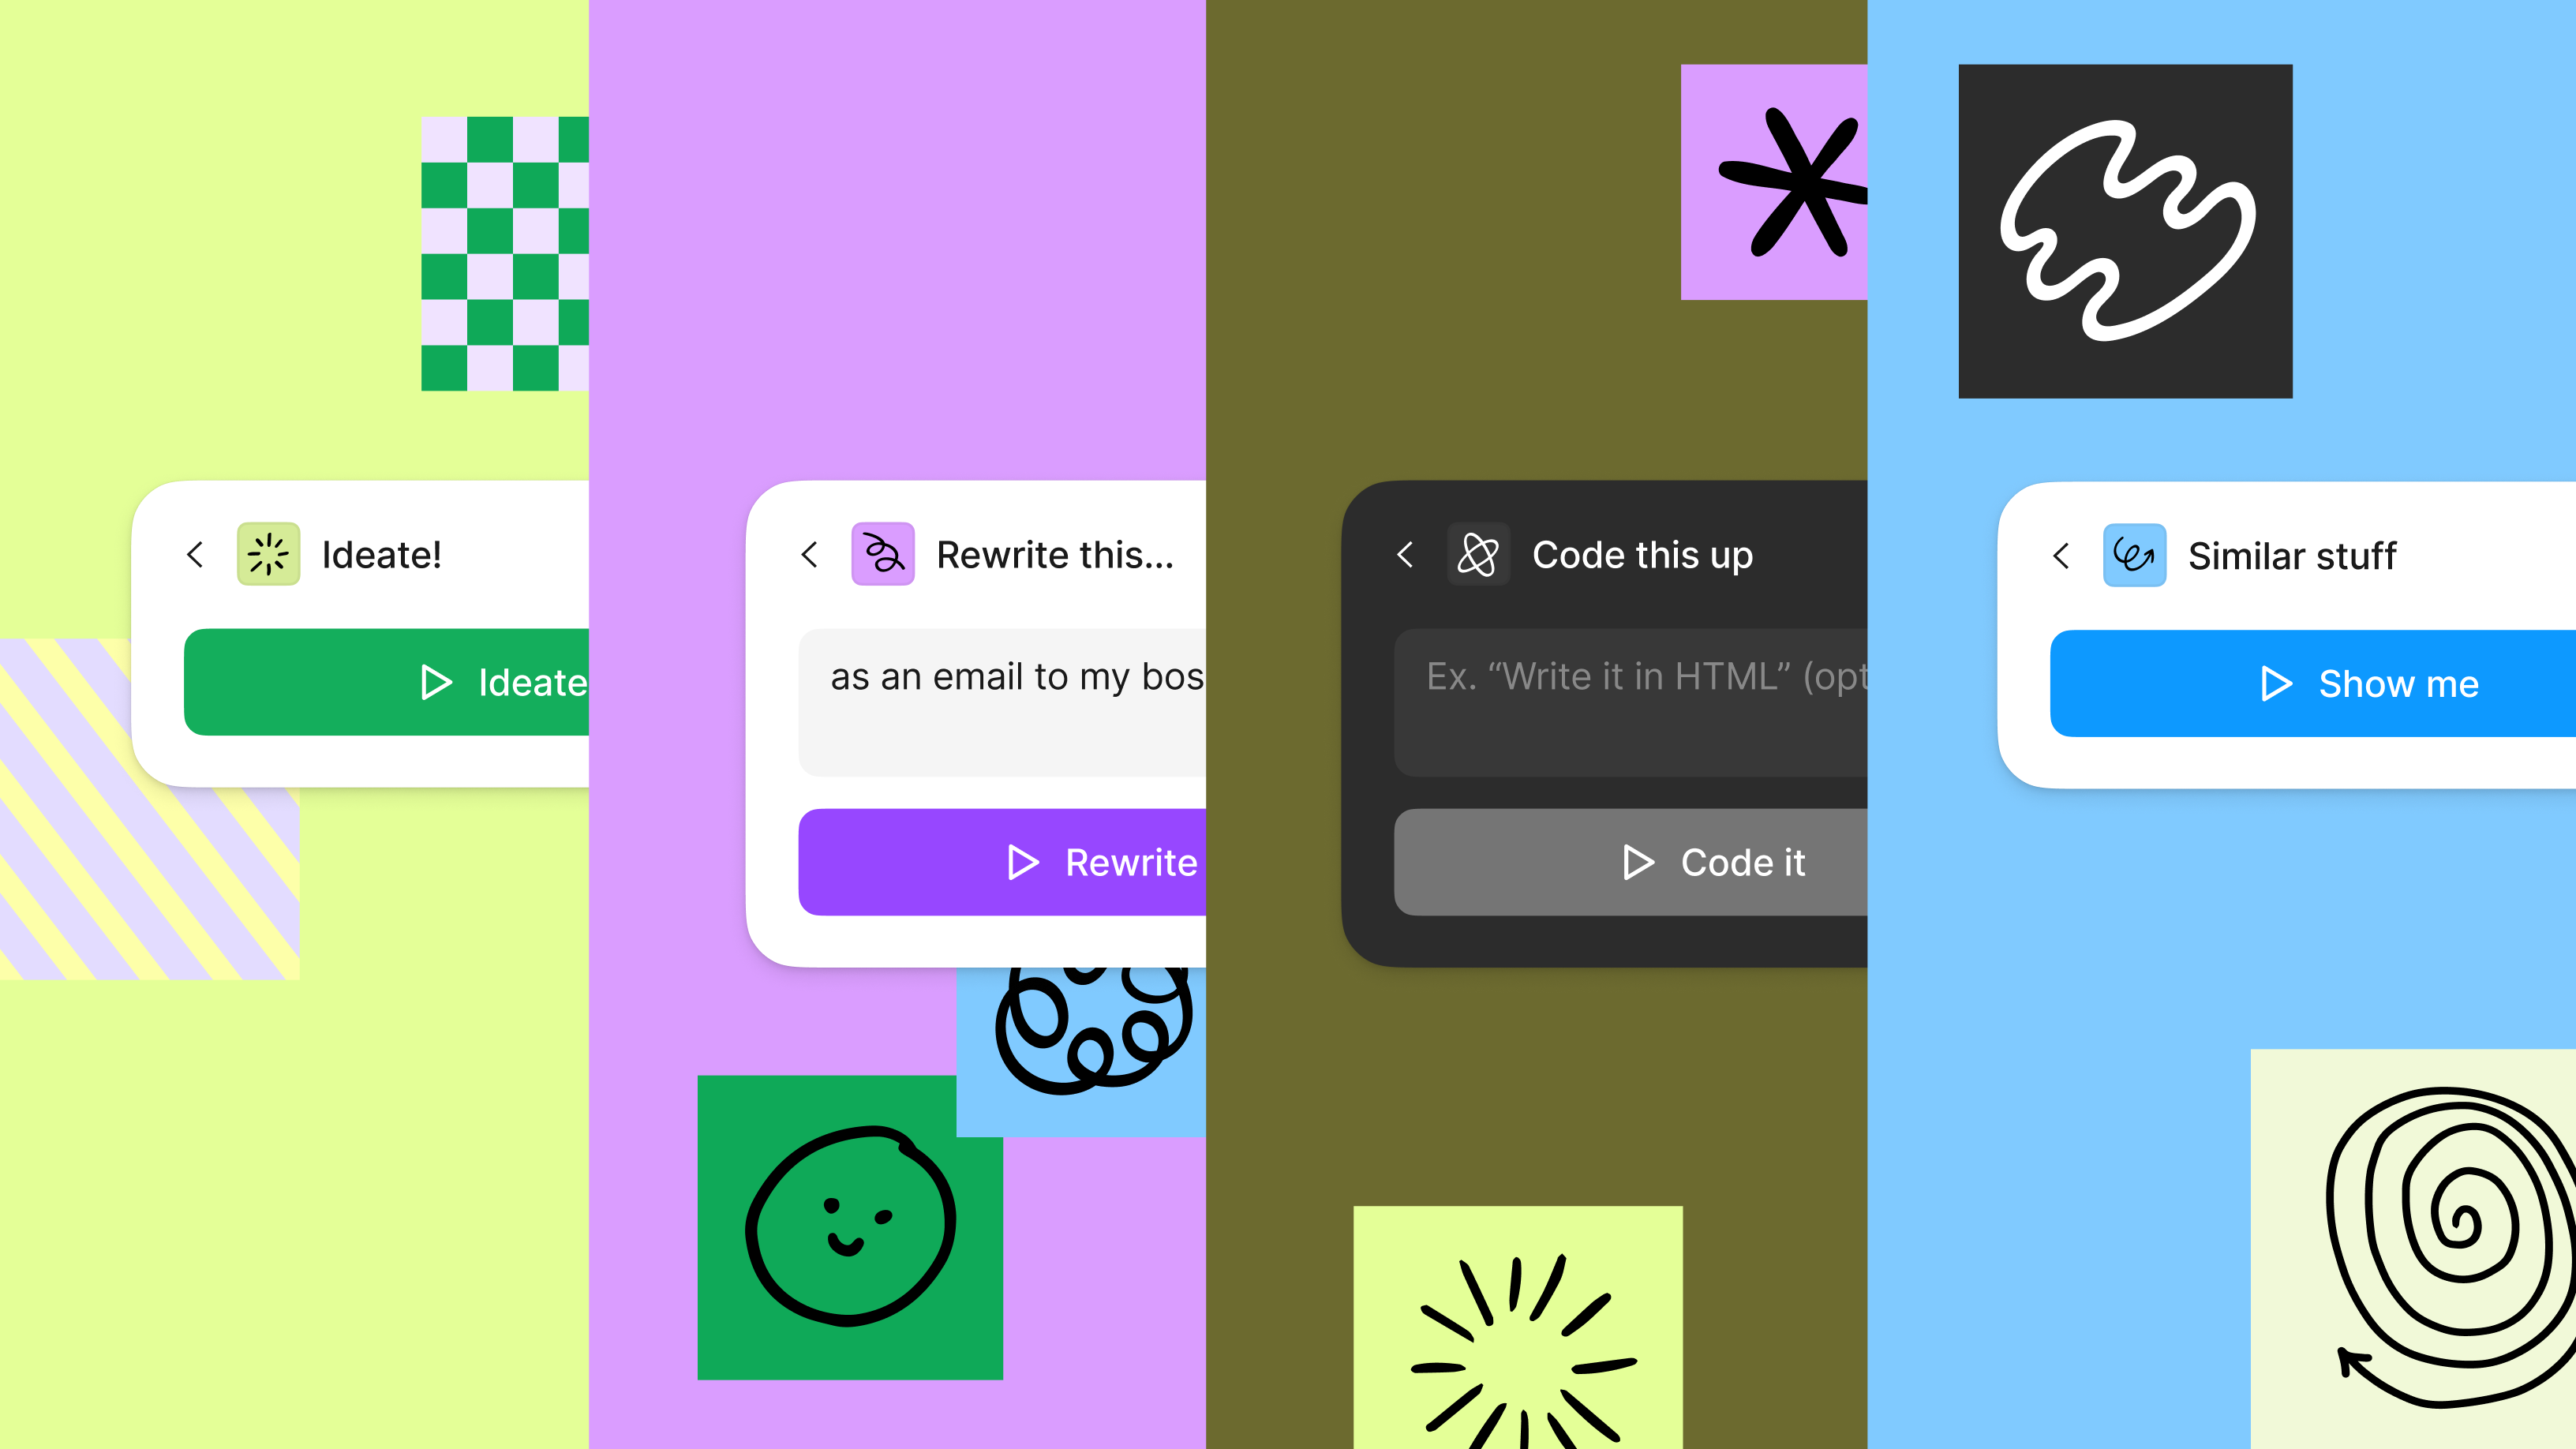
Consumers found AI through ChatGPT, so chatboxes have become the default vehicle for AI features. But chat isn't always the ideal interface. “There are so many missed opportunities when we ‘talk’ to ChatGPT—what identity it has, how contextual it can be,” says Figma's Daniel Mejia.
Duolingo learned this lesson directly. The company initially “went all in on chat” for AI features in its language-learning app, says Edwin Bodge, Group PM of Revenue and Subscriptions. But engagement suffered, particularly given that Duolingo competes with flashy social media apps for attention. “Learners are so much more comfortable interacting with something that looks like a rich UI, a delightful UI,” he explains. The team moved features away from chat into richer UI components that match user expectations.
Trust requires perceived control
Customer attitudes toward AI range from enthusiasm to anxiety. “Most customers are what we call excito-nervous,” says Asana's Rodrigo Davies. “We have to win customers’ trust.”
LinkedIn's approach shows one path: make AI's workings transparent. Its recruitment tool uses AI to draft messages to candidates, but it surfaces exactly which fields drive the generation and lets recruiters edit those fields directly. “You can automate a ton of stuff, but the human needs to be in the driver seat,” says Shyvee Shi, Product Lead at LinkedIn.
Expect a nonlinear development path
Traditional product development follows a predictable loop — identify bugs, fix them, move on. AI doesn't behave that way. “It is very non-deterministic,” says Figma Product Manager Albert Song. “You make one change and it could regress other things, and you’re not sure exactly why.”
The FigJam AI team hit exactly that wall. “We'd make improvements somewhere and quite literally take one step forward, and two steps back,” recalls Conor Woods. The team recovered by assigning engineers as subject-matter experts for each failure area and working through them individually. But the experience underscored that AI development demands room for experimental work that doesn't fit neatly into sprints. “You have to bake in time for exploratory work. It pays off in the end,” Song says.
From prototype to production: what actually ships
The path from a promising model to a shipped feature is rarely linear. Product managers working across AI teams describe a process that hinges less on the model itself and more on the orchestration around it: clear success criteria, tight feedback loops, and honest conversations about what the model can and cannot do.
Defining “good enough” before you start
Every shipped AI feature begins with a shared definition of quality. Teams that wait until late in the cycle to evaluate model outputs often discover mismatched expectations. The practical approach is to agree on evaluation metrics early — not just offline benchmarks, but the human judgments that mirror real usage. This includes edge cases, failure modes, and the tolerance for errors in high-stakes versus low-stakes contexts.
The eval loop is the product loop
Once a model is in front of users, the evaluation cycle becomes the core development cadence. Successful teams treat user feedback as a first-class signal, routing it back into prompt tuning, retrieval adjustments, or fine-tuning pipelines. This requires instrumenting the product from day one: logging inputs, outputs, and explicit or implicit user ratings. Without this telemetry, improvements are guesswork.
Knowing when to stop tuning
A recurring pitfall is endless optimization. Models can always improve, but shipping requires a cutoff. Experienced PMs recommend setting a release bar tied to user impact rather than model perfection. If the feature meets the agreed success criteria and the failure rate falls within acceptable bounds, it is ready. Post-launch iteration then targets the most frequent or most damaging failure categories first.
Communicating capability, not confidence
User trust depends on setting accurate expectations. Interface copy, onboarding flows, and inline hints should communicate what the AI can reliably do, and where it may struggle. Teams that overpromise in marketing or UI language pay for it in support tickets and churn. The most durable pattern is to frame AI assistance as augmentative — clearly flagging uncertainty and offering a graceful manual fallback.
The human review checkpoint
For high-stakes outputs, human-in-the-loop review remains a necessary gate. The design question is how to make that review efficient: pre-filtering likely errors, presenting confidence scores, and grouping similar cases. Review workflows themselves need iteration, and they often reveal model blind spots that offline evals miss entirely.
What changes when models update
A shipped AI feature is never frozen. Underlying model versions change, and each update can subtly shift behavior. Teams need a regression suite that runs before every model swap, comparing outputs against a curated golden set. This is the same discipline as unit testing for traditional software, applied to non-deterministic outputs.
The realistic timeline
Across the projects discussed, the gap between a working prototype and a polished release consistently spans multiple quarters. The bulk of that time goes not to modeling but to integration: evaluation infrastructure, UX refinement, latency and cost optimization, and support tooling. Teams that budget for this overhead from the start are the ones that actually ship.